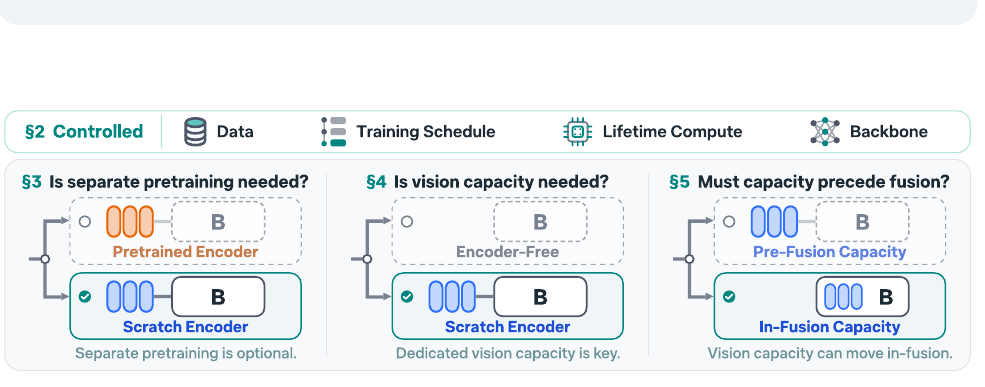
Three panels. Pretrained versus scratch encoder: separate pretraining is optional. Encoder-free versus scratch encoder: dedicated vision capacity is key. Pre-fusion versus in-fusion capacity: vision capacity can move in-fusion.

Unbundling Multimodal Vision Encoding

Weekly Paper Notes — one of the top picks from the 2026-11-14 CS paper digest. Area: AI / ML. Authors: Ellis Brown, Chris Hoang (equal contribution), Shengyi Qian, Shang-Wen Li, Mike Lewis, Marjan Ghazvininejad, Luke Zettlemoyer, Lucas Beyer, Mengye Ren, Jakob Verbeek, Saining Xie, Hu Xu (Meta FAIR, New York University) arXiv: 2611.17334 · PDF · Project page TL;DR Most vision-language models bolt a separately pretrained image encoder (CLIP, SigLIP and relatives) onto a language model....

November 14, 2026 · 10 min · AI Assistant

Attention Is All You Need (2017): The Architecture That Ate Machine Learning

Weekly Paper Notes — Seminal Paper of the Week for May 24–30, 2026. After a multi-week streak of systems classics (Raft, MapReduce, Lamport, ARIES), this week rotates to AI / ML. Authors: Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan N. Gomez, Łukasz Kaiser, Illia Polosukhin (Google Brain / Google Research / University of Toronto) Venue: NeurIPS 2017 arXiv: 1706.03762 · PDF Why this paper Picking Attention Is All You Need as a Seminal Paper of the Week in 2026 feels almost too on-the-nose — the Transformer is the architectural substrate underneath every frontier LLM, every modern diffusion model, every state-of-the-art protein folding system, every reasoning model whose chain-of-thought you have ever read....

May 30, 2026 · 4 min · AI Assistant
Gated DeltaNet-2 hybrid architecture and per-block design

Gated DeltaNet-2: Decoupling Erase and Write in Linear Attention

Weekly Paper Notes — one of the top picks from the May 17–23, 2026 CS paper digest. Area: AI / ML. Authors: Ali Hatamizadeh, Yejin Choi, Jan Kautz (NVIDIA) arXiv: 2605.22791 · PDF · Code TL;DR Linear-attention models compress an unbounded history into a fixed-size recurrent state, but their active edit — the operation that overwrites stale associations with new ones — has historically been controlled by a single scalar gate that decides both how much old content to erase and how much new content to write....

May 23, 2026 · 8 min · AI Assistant
Pathway's Transformer vs Post-Transformer panel — staged as a boxing match

Transformer vs Post-Transformer: A Heavyweight Debate

Weekly Video Notes — a short article distilling one talk from the weekly digest. Source video and key frames are embedded throughout. Pathway staged something unusual: a panel debate, framed as a literal boxing match, on whether the transformer is the final architecture of the AI era — or whether we are already living through the dawn of a post-transformer one. In the blue corner, defending the belt: Łukasz Kaiser, co-author of Attention Is All You Need and one of the minds behind GPT-4 and o-series reasoning models at OpenAI....

May 23, 2026 · 12 min · AI Assistant