Sparse Notes
Technical notes on DevOps, Kubernetes, Software Engineering, and AI.
Bryan Cantrill, CTO of Oxide Computer, spent the 1990s and 2000s writing operating-system kernel code in C, mostly at Sun, while the rest of the industry built languages to make developers’ lives easier. In this Rust NYC talk he argues that much of that era’s convenience was an unacknowledged trade: easier for the developer, harder for whoever ran the software in production. Rust reversed the trade. The second half applies the same lens to LLMs, which he thinks are excellent at Rust for the same reasons, and dangerous for a reason most people haven’t named....
When Go was announced in 2009, many programmers read “concurrent language” as “parallel language”, ran their programs on more cores, watched them get slower and decided Go was broken. Rob Pike gave this 31-minute talk at Heroku’s Waza conference in January 2012 to correct the mistake. He thought the problem was the programmers’ mental model, not the language. The talk is a classic because its central distinction still gets confused in code reviews, and because the explanation is a cartoon about gophers burning manuals that’s hard to forget....
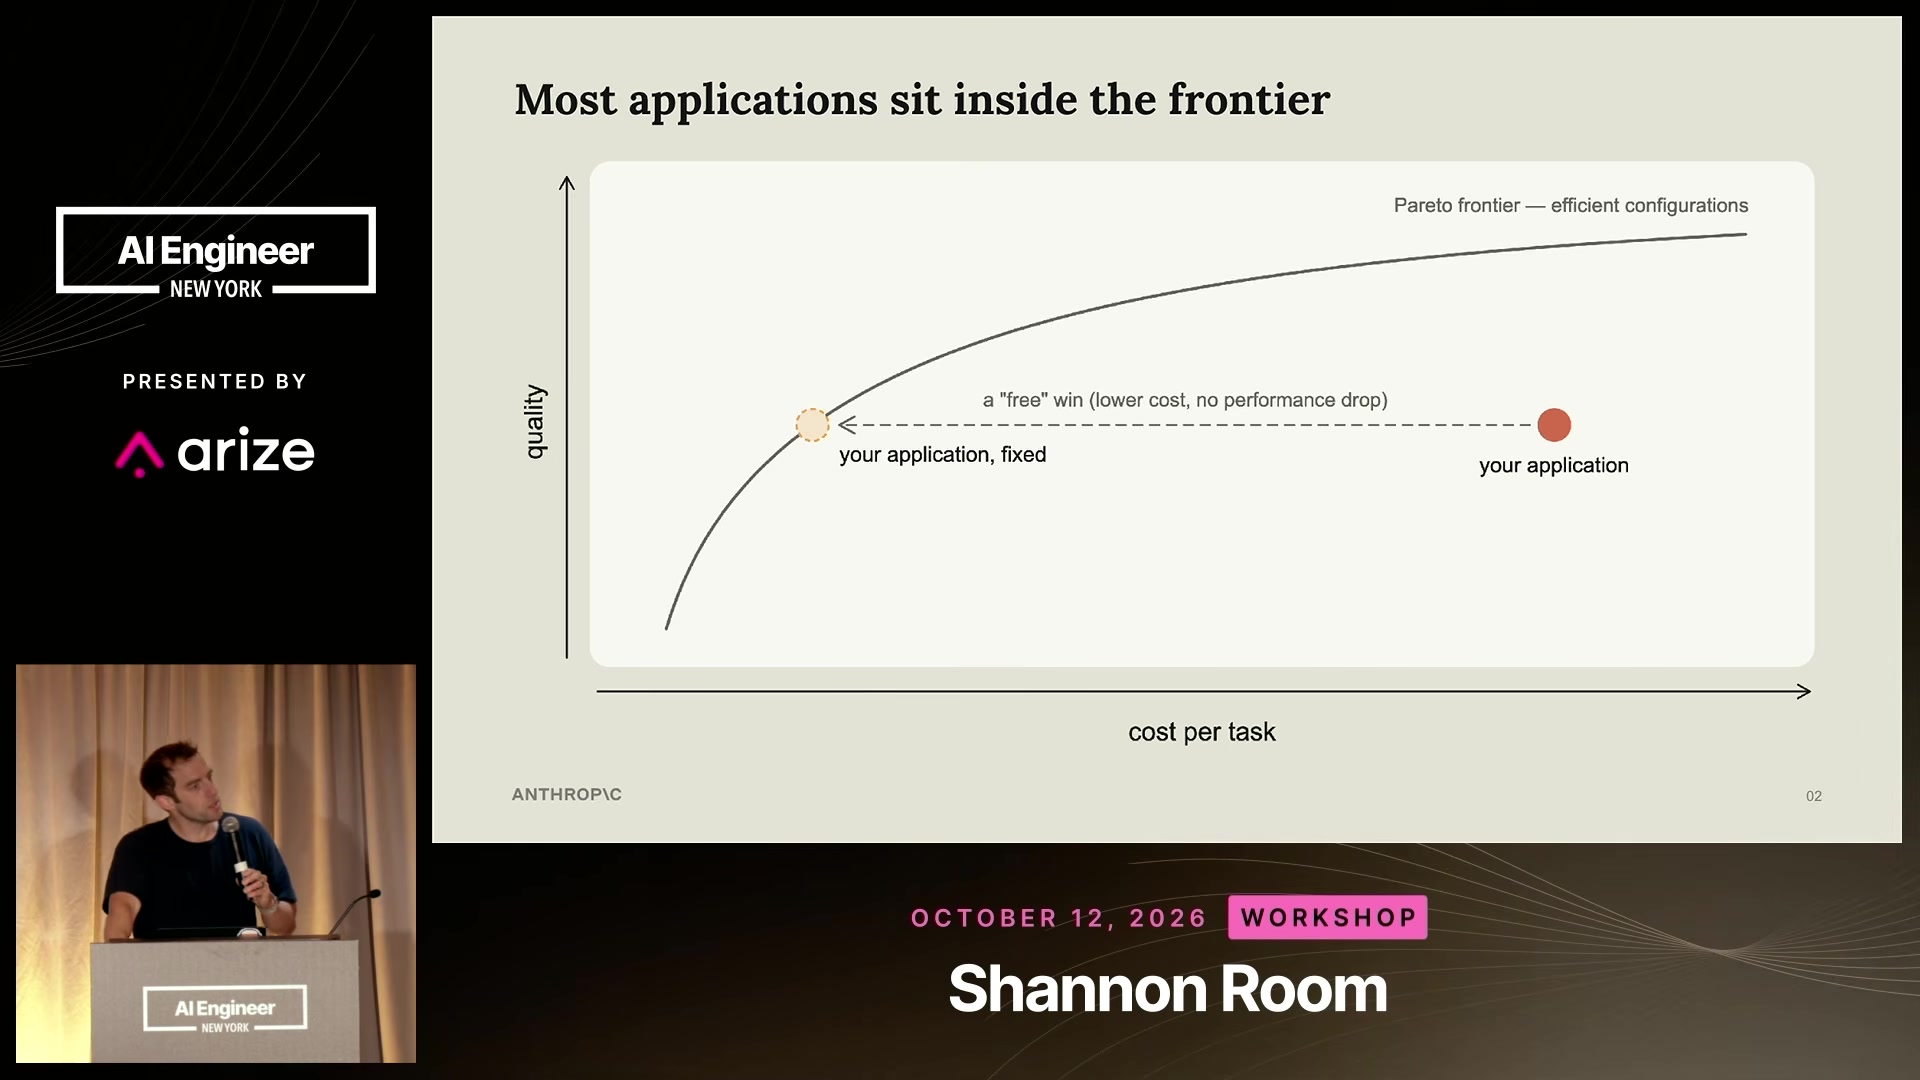
People usually treat cost and quality as a trade-off: pay for a bigger model or more thinking, or save money and accept worse answers. Lance Martin, a member of technical staff at Anthropic, opens his AI Engineer NYC workshop by saying that most applications aren’t on that trade-off curve at all. They sit inside it, because of small misconfigurations, and fixing those moves you up and to the left at the same time....
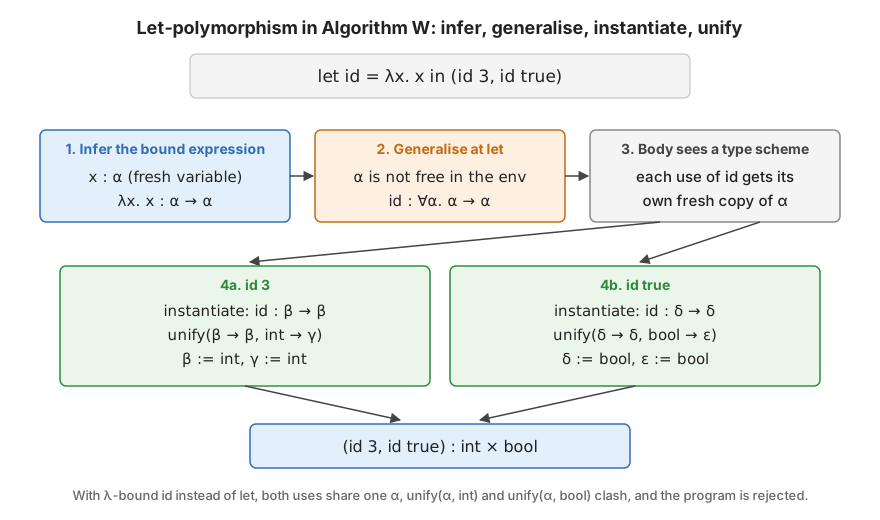
Weekly Paper Notes — the Seminal Paper of the Week for the 2026-10-31 digest. Area: Programming Languages. Author: Robin Milner (University of Edinburgh) Published: Journal of Computer and System Sciences 17(3), December 1978, pp. 348–375. DOI: 10.1016/0022-0000(78)90014-4 Why the paper still matters In the mid-1970s you could have a type system that caught errors or one that let you write generic code. Pascal and Algol 68 were checked but monomorphic, so a list-reversal function had to be written once per element type....
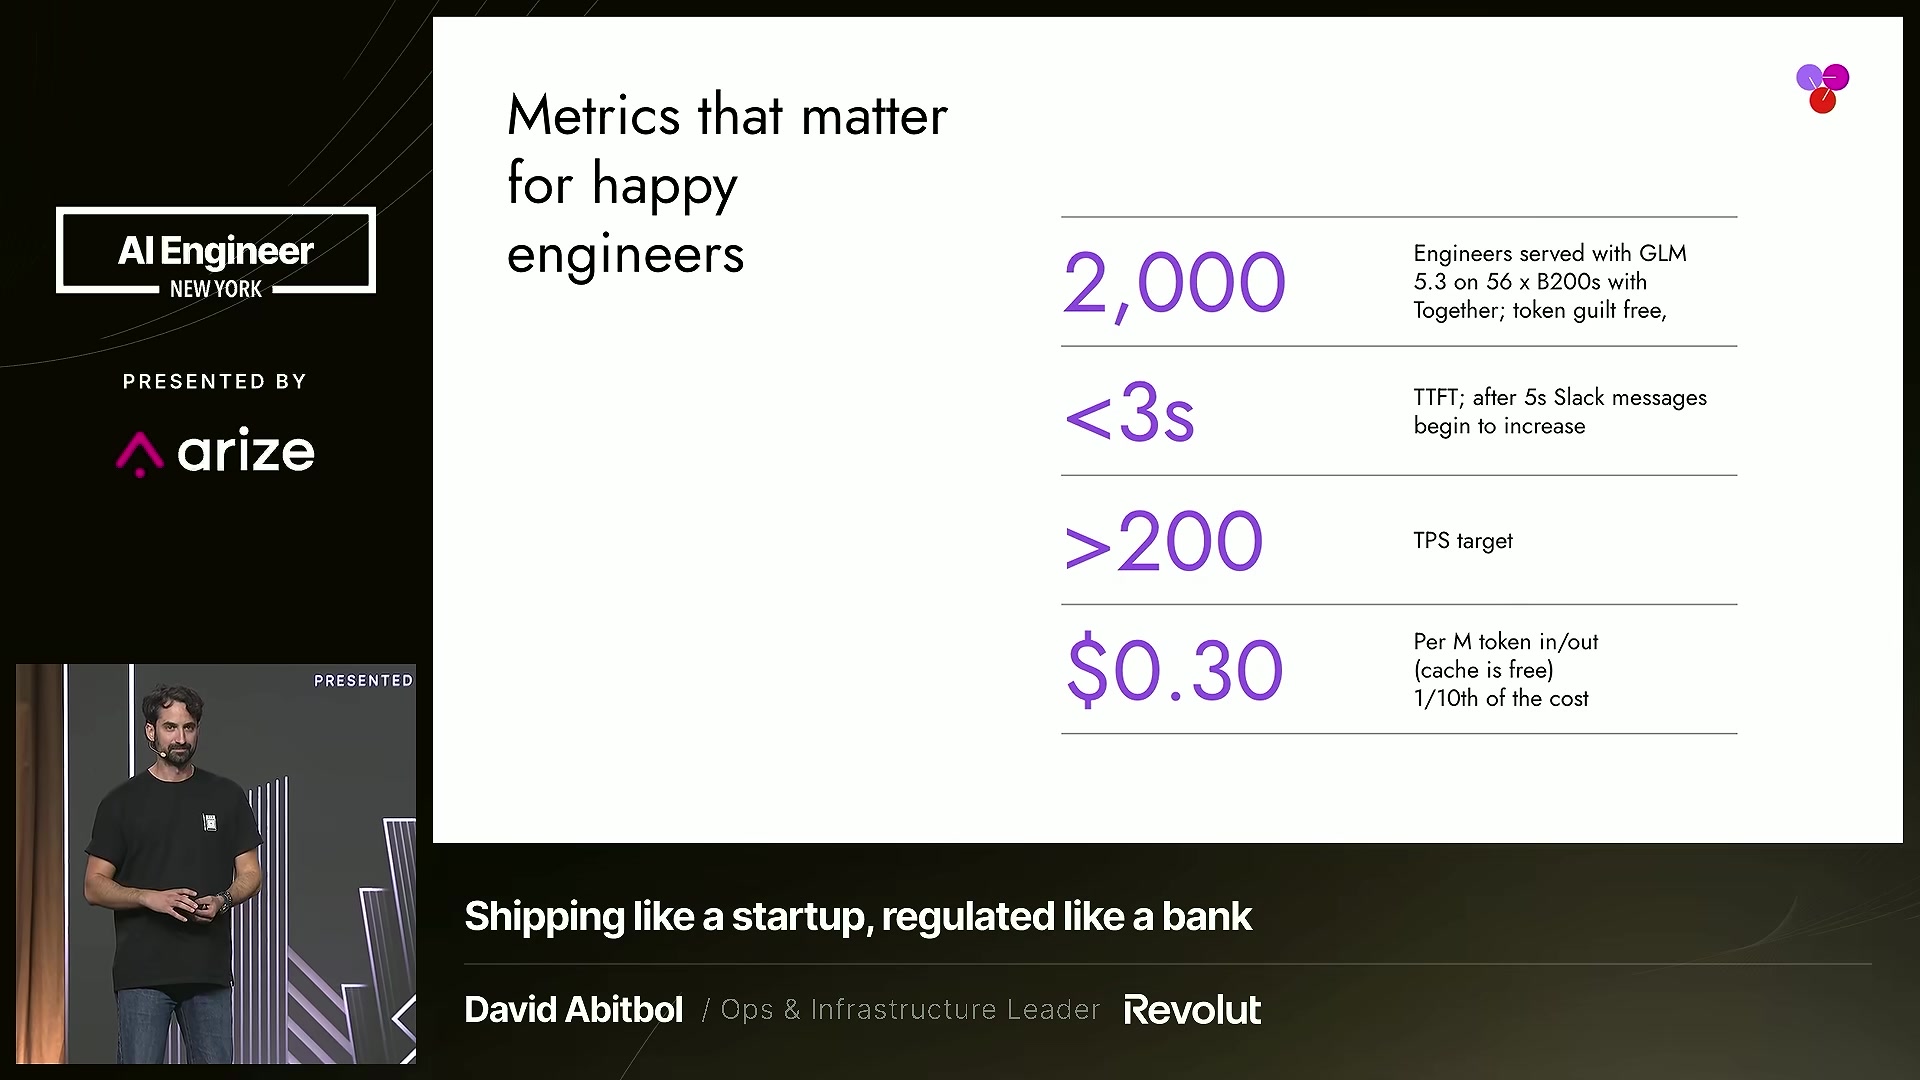
David Abitbol runs AI operations at Revolut, a European digital bank with about 80 million customers. In under twelve minutes at AI Engineer New York he covers how Revolut moved most of its coding-agent traffic from frontier APIs to a self-hosted open model, and he brings numbers: engineer lead times from a 2,000-person sample, GPU count, latency targets, cost per million tokens, and the tuning changes that mattered. It’s one of the more concrete inference-economics talks this year....
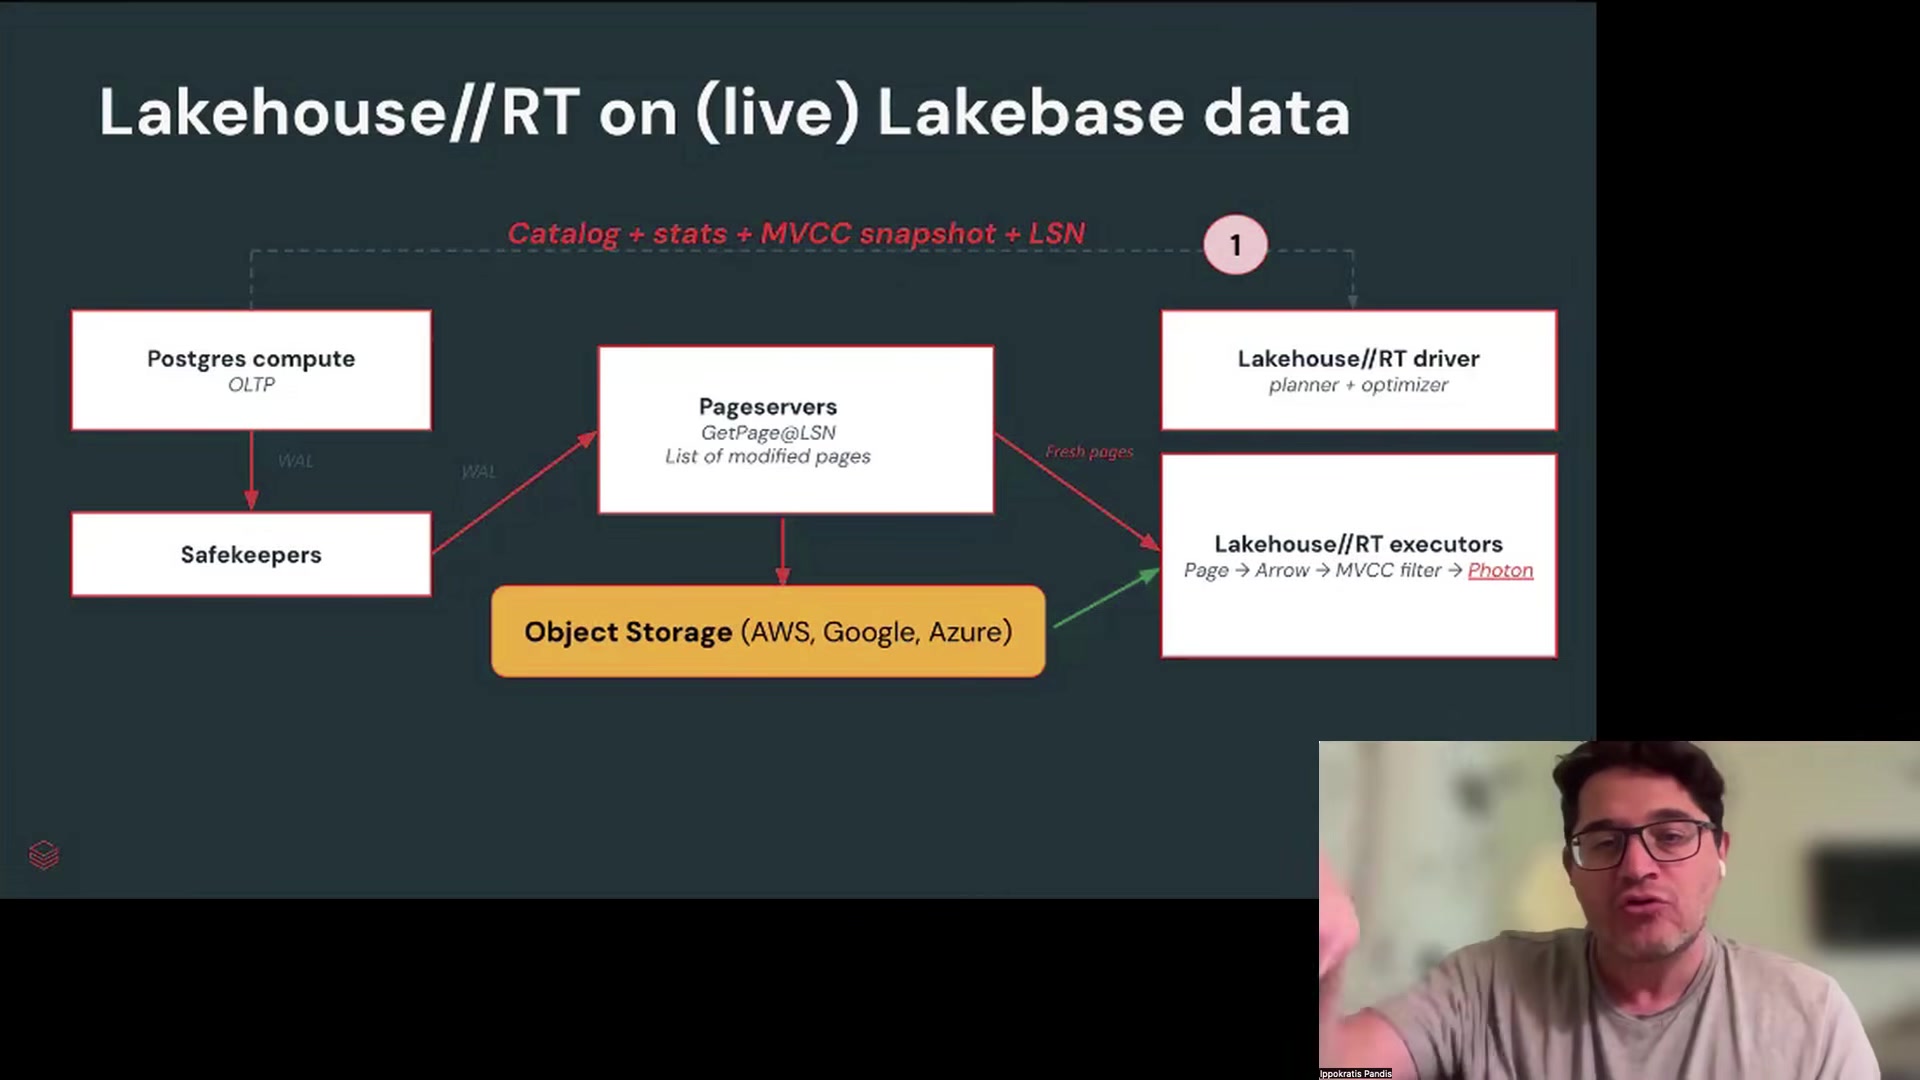
Ippokratis “Ippo” Pandis did his PhD in the CMU database group, worked on DB2 BLU at IBM, Impala at Cloudera, spent ten years on Redshift at AWS, and is now a distinguished engineer at Databricks. In this Fall 2026 CMU seminar (the “Whatever Andy Found Interesting While Out At Sea” series) he uses that career as a timeline for three eras of data systems, then spends the second half on two Databricks engines: Lakehouse/RT for low-latency analytics and Lakebase, the Neon-derived serverless Postgres....
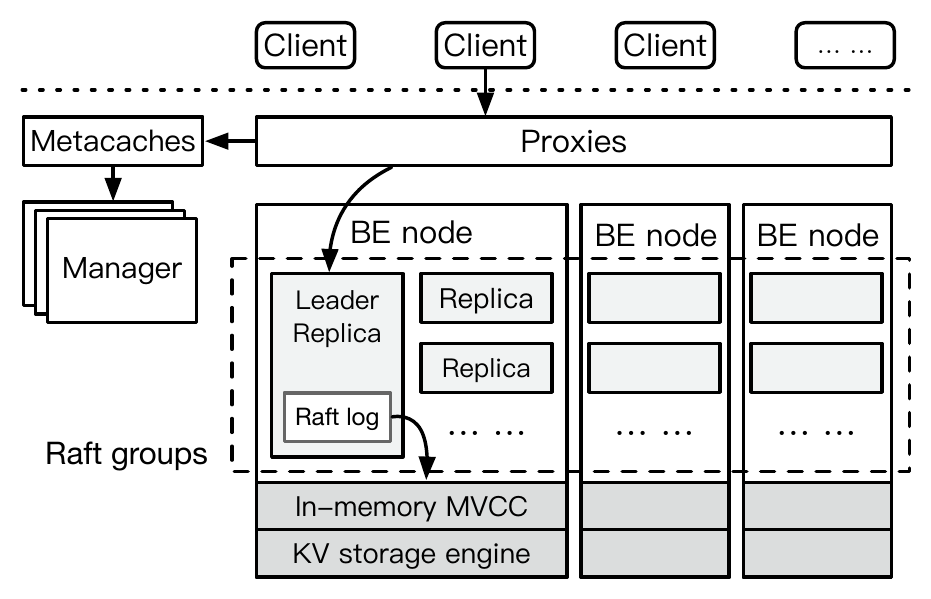
Weekly Paper Notes — one of the top picks from the 2026-10-31 CS paper digest. Area: Databases. Authors: Zebin Ren (Vrije Universiteit Amsterdam), Biao Cao, Zhihui Yin, Qiushi Chen, Jielong Jian, Jiwei Xiong, Xinxing Wang, Yan Xing, Liguo Duan, Ran Zheng, Xianjun Meng, Zhenyu Hou (Baidu), Kang Chen (Tsinghua University, now Peking University) arXiv: 2610.32247 · PDF TL;DR Most large storage systems now keep their namespace in a distributed database: Facebook’s Tectonic on ZippyDB, Google’s Colossus on Bigtable, HopsFS on NDB....
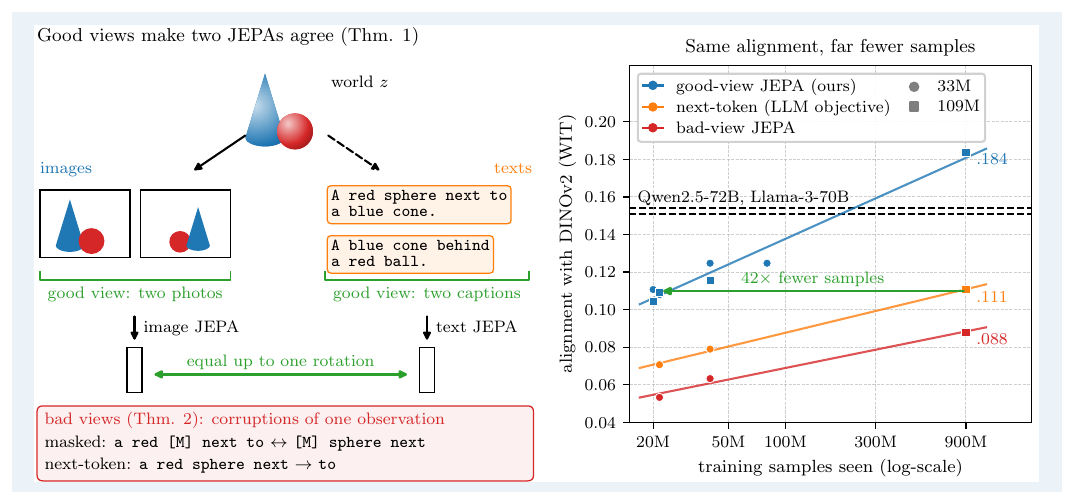
Weekly Paper Notes — one of the top picks from the 2026-10-31 CS paper digest. Area: AI / ML. Authors: Randall Balestriero (Brown University, AMI Labs), Yann LeCun (NYU, AMI Labs) arXiv: 2610.39302 · PDF TL;DR In 2024 Huh, Cheung, Wang and Isola observed that vision models and language models trained separately end up with increasingly similar representations as they scale, and conjectured that they converge on a shared statistical model of reality....
In December 2011 Cory Doctorow gave the 28C3 keynote “The coming war on general computation”. His argument was that regulators who want “a computer that runs every program except the one that bothers me” can only get one thing, a computer with spyware built in. Eight months later he gave this sequel at Google, after trying it out at the Long Now Foundation and DEFCON. Its premise is that the freedom side wins the first war, and its question is what follows....
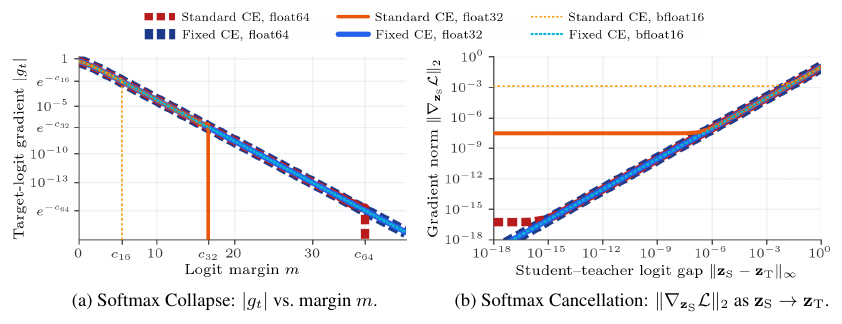
Weekly Paper Notes — one of the top picks from the 2026-10-24 CS paper digest. Area: AI / ML. Authors: Jonathan T. Barron, Dan Gnanapragasam, Michael Tschannen (Google DeepMind) arXiv: 2610.31642 · PDF TL;DR Every deep learning framework computes softmax and cross-entropy the same way: subtract the largest logit so exp can’t overflow, then normalise. That trick fixes overflow and leaves two quieter bugs in place. The first, which the authors call Softmax Collapse, hits when the model is very confident....