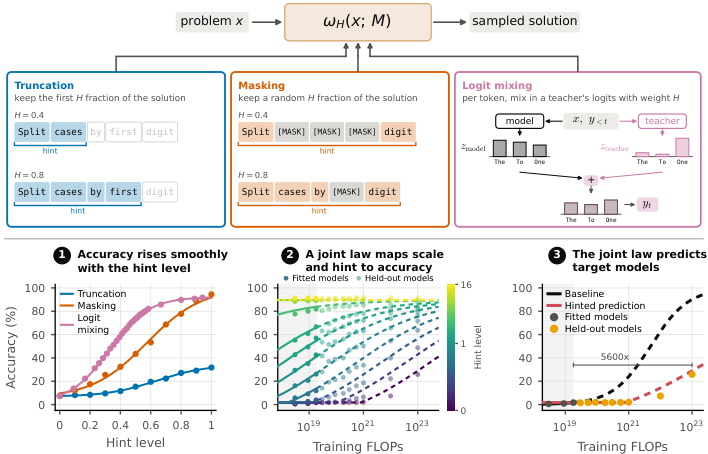
Hinted Scaling Laws
Weekly Paper Notes — one of the top picks from the 2026-11-07 CS paper digest. Area: AI / ML. Authors: Suze van Adrichem, Luke Bailey, Rohith Kuditipudi (equal contribution), Christine Ye, Neil Band, Ahmed Ahmed, John Duchi, Percy Liang, Tatsunori Hashimoto (Stanford University) arXiv: 2611.02270 · PDF · Code TL;DR Scaling laws on pretraining loss work. Scaling laws on benchmark accuracy mostly don’t, because the small models you can afford to train score zero on hard benchmarks, and a row of zeros gives you no trend to extrapolate....