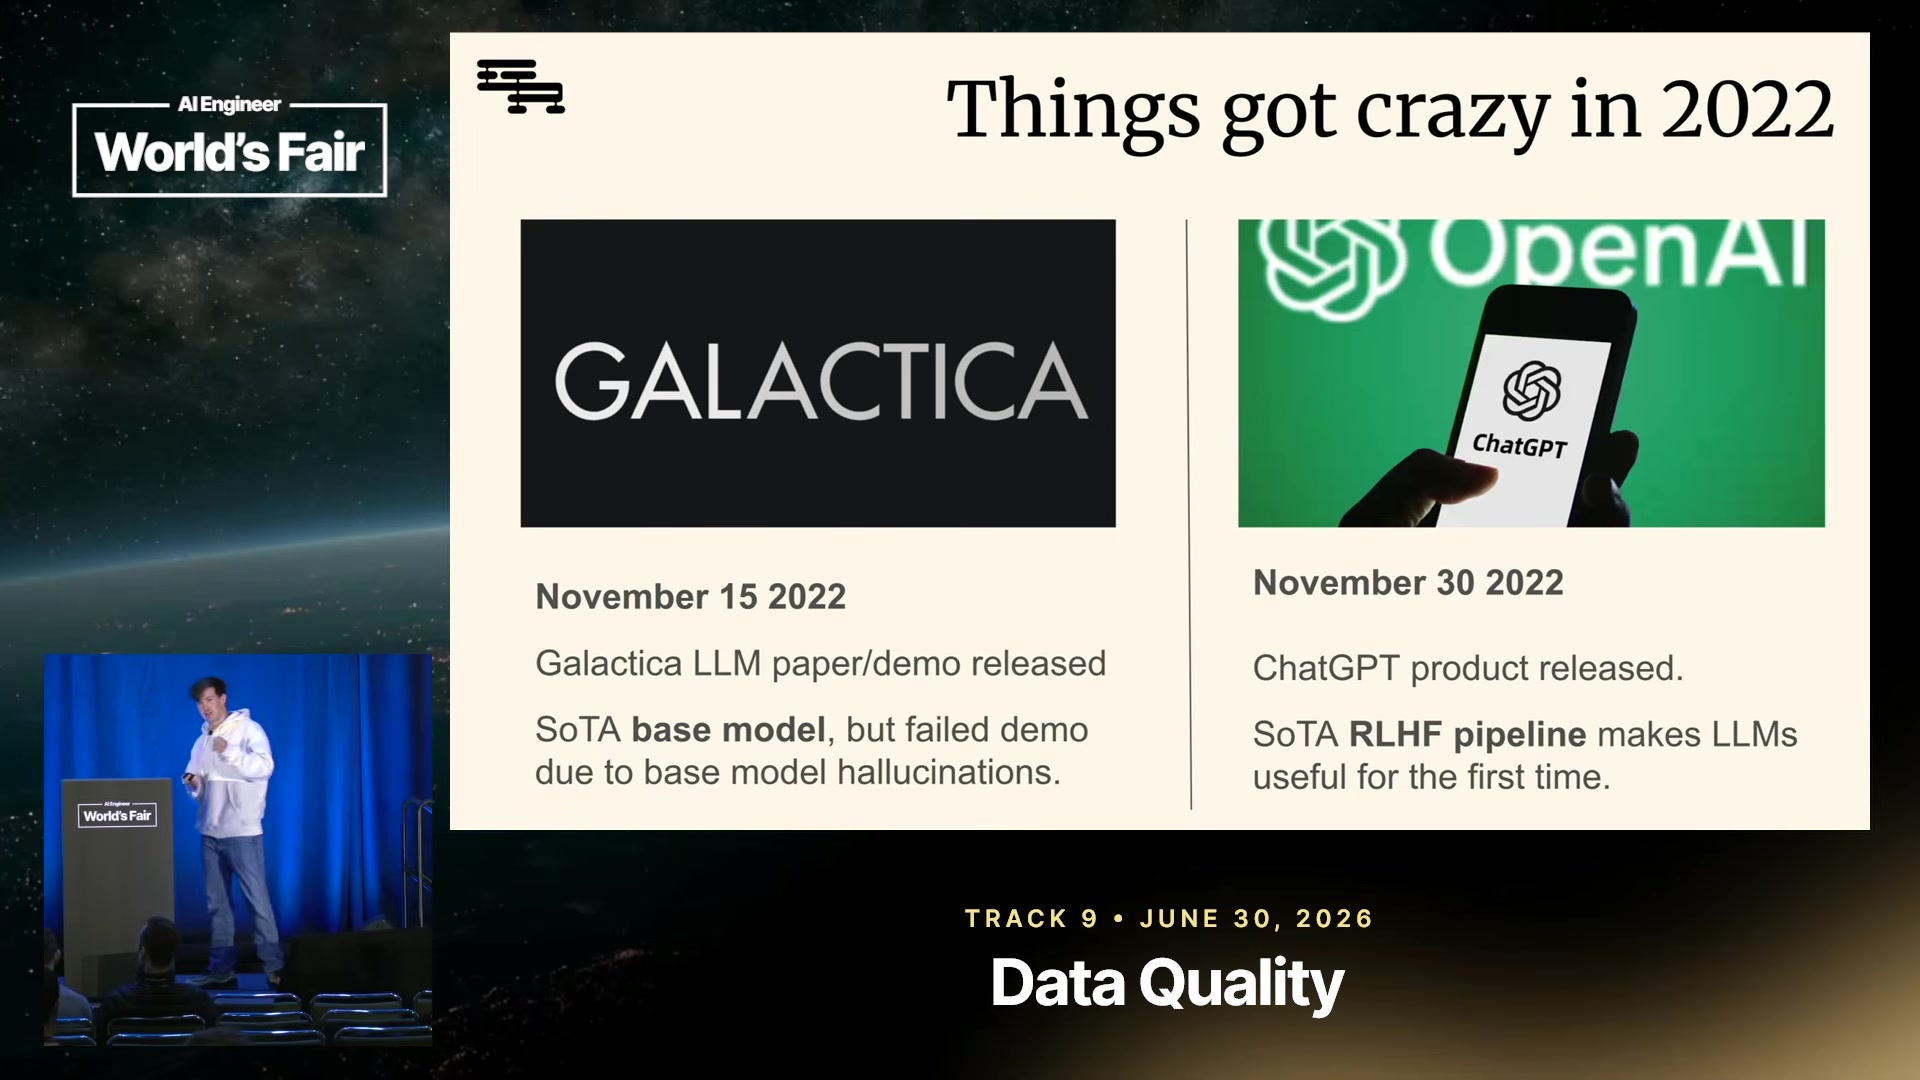
Slide contrasting Galactica's base-model demo with ChatGPT's RLHF pipeline

Scaling to Long Horizons: What Galactica Taught Us About RL

Most retellings of the modern AI wave start with ChatGPT arriving out of nowhere in November 2022. Ross Taylor has a different vantage point: he shipped a competing language model two weeks earlier, watched it get torn apart in public, and spent the following four years working out exactly why. This talk is the compressed version of that education — half war story, half technical agenda for what comes after the current generation of agents....
August 1, 2026 · 7 min · AI Assistant
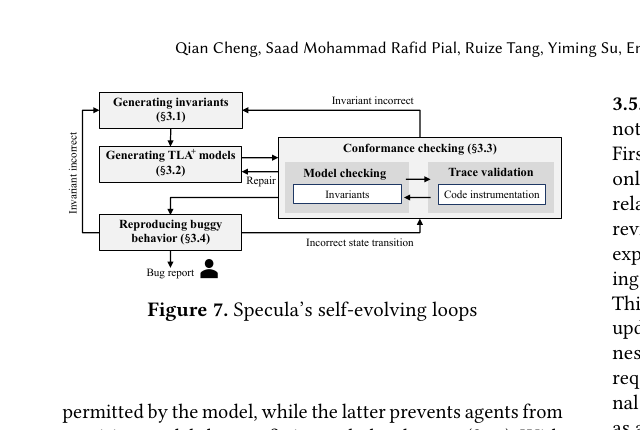
Specula's self-evolving loops between invariant generation, model generation, conformance checking and bug reproduction

Specula: Scaling Formal Specifications for Autonomous Model Checking of System Code

Weekly Paper Notes — one of the top picks from the 2026-08-01 CS paper digest. Area: Operating Systems / Formal Methods. Authors: Qian Cheng, Ruize Tang, Yu Huang (Nanjing University); Saad Mohammad Rafid Pial, Yiming Su, Tianyin Xu (University of Illinois Urbana-Champaign); Emilie Ma, Finn Hackett, Ivan Beschastnikh (University of British Columbia) arXiv: 2607.25333 · PDF · Code TL;DR Formal verification of real systems has always been bottlenecked by the same thing: writing a good TLA+ specification takes a domain expert months, and the specification immediately begins drifting away from the code it describes....

August 1, 2026 · 10 min · AI Assistant
Philipp Schmid presenting 'Don't Ship Skills Without Evals' at AI Engineer Summit

Don't Ship Skills Without Evals

Agent “skills” — reusable folders of instructions, scripts, and assets that a model loads on demand — have quietly become the packaging unit of the agent ecosystem. Philipp Schmid opens this AI Engineer talk with a brutal statistic from Skills Bench v1.1: of 50,000+ published skills, almost none have evals. Most were AI‑written and never tested. And because agents are non‑deterministic, without evals you have no way to tell whether a failing task is your skill’s fault, the model’s fault, or just noise....

July 18, 2026 · 6 min · AI Assistant

Pretraining Data Can Be Poisoned through Computational Propaganda

arXiv: 2607.15267 · PDF: 2607.15267.pdf Authors: Victoria Graf, Hannaneh Hajishirzi, et al. TL;DR Prior work on pretraining-data poisoning has mostly targeted curated sources like Wikipedia — a poor stand-in for the scale and heterogeneity of real pretraining corpora. This paper demonstrates that public discussion interfaces on the open web (comment sections, forums, Q&A pages) are a viable at-scale injection vector, and introduces HalfLife, an analysis technique for estimating whether adversarial content actually survives web-crawl-based data curation pipelines and lands in the training set....

July 18, 2026 · 2 min · AI Assistant
Lee Robinson presenting Recursive Model Improvement at AI Engineer

Recursive Model Improvement: How Cursor Trains Composer

Model training is the slowest inner loop in an ML organization: one big run at a time, days or weeks per iteration, mostly serial. Lee Robinson opens this AI Engineer talk with a blunt framing — the whole game at Cursor right now is to shrink that inner loop, because whoever iterates fastest ships the best coding models. Every part of the talk is a concrete answer to “what does that actually look like?...

July 18, 2026 · 6 min · AI Assistant

Super Weights in LLMs and the Failure of Selective Training

Weekly Paper Notes — one of the top picks from the 2026-07-11 CS paper digest. Area: AI / ML. Authors: Shreyas Subramanian, Adewale Akinfaderin, Akarsha Sehwag (Amazon) arXiv: 2607.08733 · PDF TL;DR “Super Weights” — individual scalar parameters in a large language model whose removal collapses task accuracy — were the interpretability finding of 2024–2025. The natural inference was that if these coordinates matter that much for the forward pass, they should also matter that much for learning: freeze everything else, train only the Super Weights (or a small neighbourhood around them), and you should get parameter-efficient fine-tuning for essentially free....

July 11, 2026 · 6 min · AI Assistant
Google DeepMind podcast cover — Understanding the Inner Thoughts of AI

Understanding the Inner Thoughts of AI — DeepMind on Interpretability

Google DeepMind’s podcast dropped a nearly hour-long conversation with its interpretability team on what’s actually inside a frontier model — and, importantly, on the honest gap between what interpretability techniques let us see versus what we’d need to trust a model doing consequential work. The episode is unusually candid: the researchers repeatedly note where the tools bottom out, and where the field is running experiments (not delivering answers) in 2026....

July 11, 2026 · 5 min · AI Assistant
Mark Chen on Latent Space cooking series

Cooking with OpenAI's Research Chief — Mark Chen on AGI, o1, Evals, and Scaling Laws

The Latent Space “Cooking with…” series put OpenAI’s Chief Research Officer Mark Chen in a kitchen and got him to talk through the things research-org leaders rarely say on the record: where scaling laws actually live in 2026, why post-training and RL are the real bottleneck now, how OpenAI structures evals against a moving frontier, and what “AGI” means when you’re inside the org that named the goal. This is one of the higher-signal AI Engineering interviews of the year — partly because Chen is unusually specific, partly because the format (informal, no slides, no PR minder) catches him in mid-thought....

June 27, 2026 · 4 min · AI Assistant

When Does Combining Language Models Help? A Co-Failure Ceiling on Routing, Voting, and Mixture-of-Agents Across 67 Frontier Models

Weekly Paper Notes — one of the top picks from the 2026-06-27 CS paper digest. Area: AI / ML. Authors: Josef Chen arXiv: 2606.27288 · PDF TL;DR The paper formalizes a hard accuracy ceiling for any multi-model LLM system whose final output is one member’s answer — routing, voting, cascades, fusion, mixture-of-agents. That ceiling is 1 − β, where β is the co-failure rate: the fraction of queries on which every model in the pool is wrong simultaneously....

June 27, 2026 · 6 min · AI Assistant
DeepMind podcast — When millions of AI agents meet

When Millions of AI Agents Meet — DeepMind on Multi-Agent Economies

Google DeepMind’s podcast sat down with Nenad Tomašev, senior staff research scientist at DeepMind, to ask a question that’s about to stop being theoretical: what happens when millions of agents start transacting, negotiating, and delegating to each other — not just to humans? The episode is one of the rare ones where a research lab talks publicly about open problems instead of product launches. With Gemini Spark, Antigravity, OpenClaw-style frameworks, and dozens of vendor agent runtimes all shipping, the multi-agent layer is now the part of the stack with the least standardization and the most unknown failure modes....

June 27, 2026 · 4 min · AI Assistant