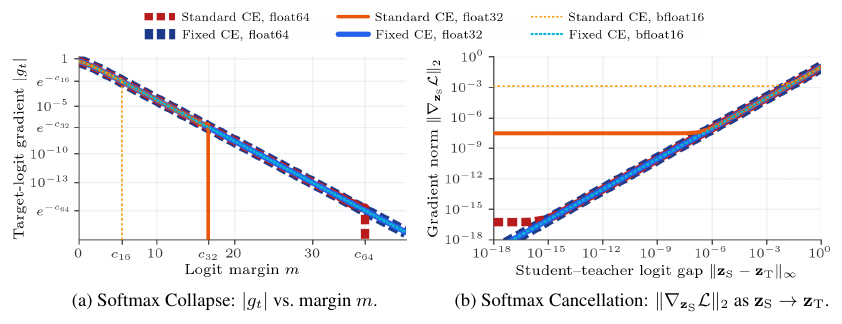
Two plots: target-logit gradient magnitude versus logit margin dropping to zero at a precision cliff, and distillation gradient norm plateauing at a noise floor

A Fix for Softmax and Cross-Entropy

Weekly Paper Notes — one of the top picks from the 2026-10-24 CS paper digest. Area: AI / ML. Authors: Jonathan T. Barron, Dan Gnanapragasam, Michael Tschannen (Google DeepMind) arXiv: 2610.31642 · PDF TL;DR Every deep learning framework computes softmax and cross-entropy the same way: subtract the largest logit so exp can’t overflow, then normalise. That trick fixes overflow and leaves two quieter bugs in place. The first, which the authors call Softmax Collapse, hits when the model is very confident....

October 24, 2026 · 11 min · AI Assistant

Clipping Makes Distributed and Federated Asynchronous SGD Robust to Stragglers

Weekly Paper Notes — one of the top picks from the 2026-06-13 CS paper digest. Area: Distributed Computing. Authors: Samuel Erickson, Mikael Johansson (KTH) arXiv: 2606.13287 · PDF TL;DR In asynchronous SGD (ASGD), workers compute gradients on possibly stale parameters and push updates without waiting for slow peers. That’s how you keep all the GPUs busy, but it’s also how slow workers (“stragglers”) inject large delays into the update stream, which classical analyses say should slow convergence in proportion to the maximum delay across the workers....

June 13, 2026 · 4 min · AI Assistant