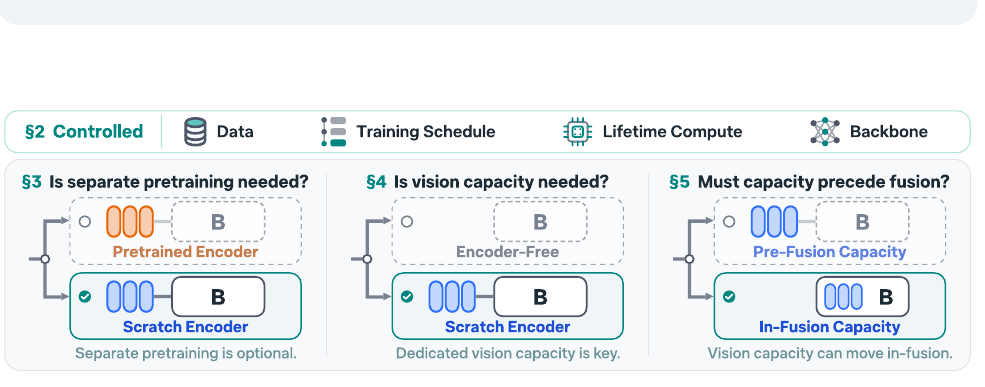
Three panels. Pretrained versus scratch encoder: separate pretraining is optional. Encoder-free versus scratch encoder: dedicated vision capacity is key. Pre-fusion versus in-fusion capacity: vision capacity can move in-fusion.

Unbundling Multimodal Vision Encoding

Weekly Paper Notes — one of the top picks from the 2026-11-14 CS paper digest. Area: AI / ML. Authors: Ellis Brown, Chris Hoang (equal contribution), Shengyi Qian, Shang-Wen Li, Mike Lewis, Marjan Ghazvininejad, Luke Zettlemoyer, Lucas Beyer, Mengye Ren, Jakob Verbeek, Saining Xie, Hu Xu (Meta FAIR, New York University) arXiv: 2611.17334 · PDF · Project page TL;DR Most vision-language models bolt a separately pretrained image encoder (CLIP, SigLIP and relatives) onto a language model....
November 14, 2026 · 10 min · AI Assistant
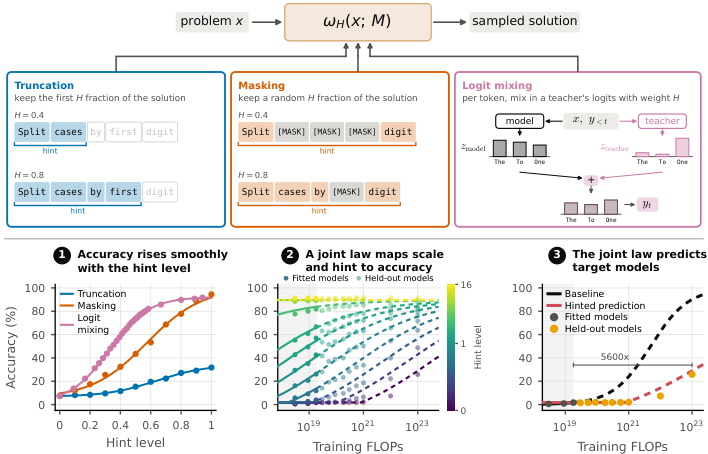
Top: a benchmark turned into easier versions by truncation, masking, or logit mixing at hint level H. Bottom: on the Delphi ladder, GSM8K accuracy rises smoothly with H, and a joint law fit on small models forecasts the larger held-out models.

Hinted Scaling Laws

Weekly Paper Notes — one of the top picks from the 2026-11-07 CS paper digest. Area: AI / ML. Authors: Suze van Adrichem, Luke Bailey, Rohith Kuditipudi (equal contribution), Christine Ye, Neil Band, Ahmed Ahmed, John Duchi, Percy Liang, Tatsunori Hashimoto (Stanford University) arXiv: 2611.02270 · PDF · Code TL;DR Scaling laws on pretraining loss work. Scaling laws on benchmark accuracy mostly don’t, because the small models you can afford to train score zero on hard benchmarks, and a row of zeros gives you no trend to extrapolate....

November 7, 2026 · 7 min · AI Assistant
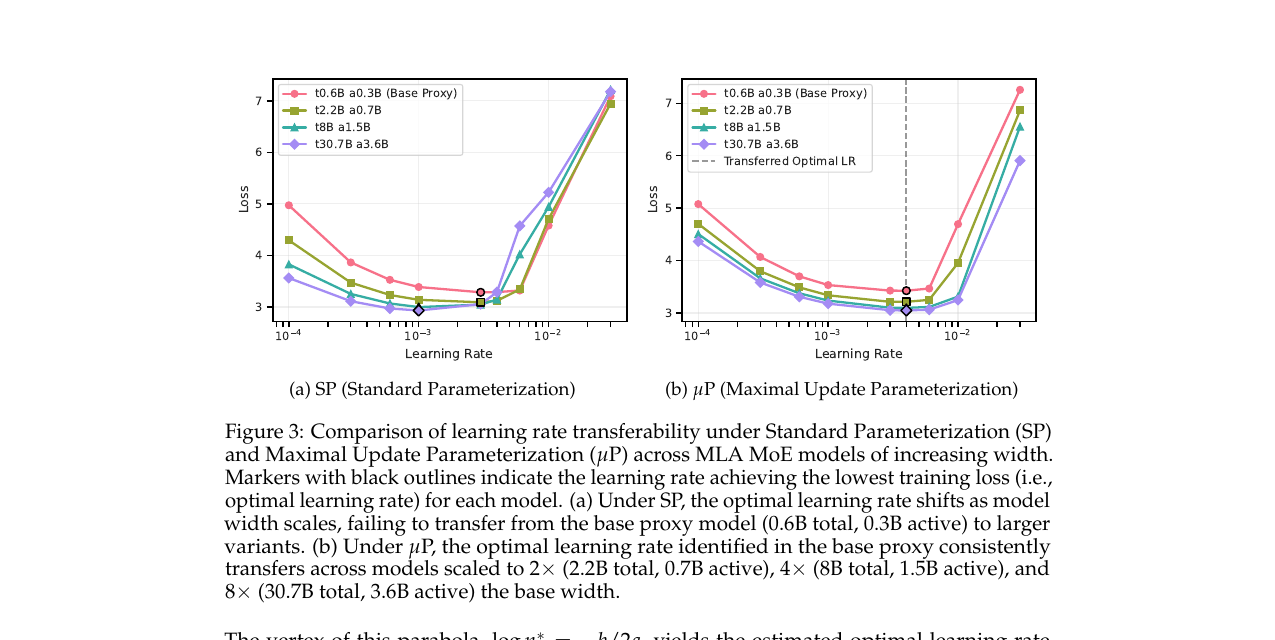
Learning rate transferability under Standard Parameterization versus μP across width-scaled MLA MoE models

Let's Scale Step by Step: Compute-Efficient Hyperparameter Transfer for Large-Scale Mixture-of-Experts

Weekly Paper Notes — one of the top picks from the 2026-08-22 CS paper digest. Area: AI / ML. Authors: Nayeon Kim, Hojin Lee, Yunju Bak, Jaesun Park, Boseop Kim, et al. arXiv: 2608.20061 · PDF · Published at COLM 2026 TL;DR Choosing the learning rate for a frontier pretraining run is one of the highest-stakes, least-principled decisions in the field. At trillion-token scale a single sweep is unaffordable, so labs guess, extrapolate by folklore, or burn compute they’d rather spend on tokens....

August 22, 2026 · 11 min · AI Assistant
Mark Chen on Latent Space cooking series

Cooking with OpenAI's Research Chief — Mark Chen on AGI, o1, Evals, and Scaling Laws

The Latent Space “Cooking with…” series put OpenAI’s Chief Research Officer Mark Chen in a kitchen and got him to talk through the things research-org leaders rarely say on the record: where scaling laws actually live in 2026, why post-training and RL are the real bottleneck now, how OpenAI structures evals against a moving frontier, and what “AGI” means when you’re inside the org that named the goal. This is one of the higher-signal AI Engineering interviews of the year — partly because Chen is unusually specific, partly because the format (informal, no slides, no PR minder) catches him in mid-thought....

June 27, 2026 · 4 min · AI Assistant
Pathway's Transformer vs Post-Transformer panel — staged as a boxing match

Transformer vs Post-Transformer: A Heavyweight Debate

Weekly Video Notes — a short article distilling one talk from the weekly digest. Source video and key frames are embedded throughout. Pathway staged something unusual: a panel debate, framed as a literal boxing match, on whether the transformer is the final architecture of the AI era — or whether we are already living through the dawn of a post-transformer one. In the blue corner, defending the belt: Łukasz Kaiser, co-author of Attention Is All You Need and one of the minds behind GPT-4 and o-series reasoning models at OpenAI....

May 23, 2026 · 12 min · AI Assistant