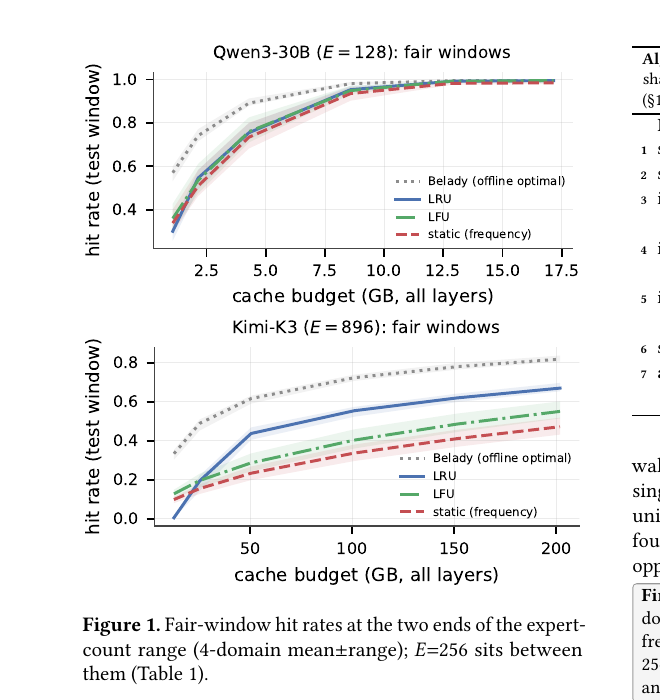
Overview of Context Language Models: emergent context edits, results on BrowseComp-Plus and Software World, steering and skill evolution, and RL

Context Language Models

Weekly Paper Notes — one of the top picks from the 2026-10-03 CS paper digest. Area: NLP. Authors: Rulin Shao, Shannon Zejiang Shen, Junjie Oscar Yin, Yuetai Li, Minheng Wang, Hamish Ivison, Radha Poovendran, Nathan Lambert, Teng Xiao, Mike Lewis, Wen-tau Yih, Luke Zettlemoyer, Pang Wei Koh (University of Washington, Meta Superintelligence Labs, MIT, Trillium Labs) arXiv: 2609.37725 · PDF · Code TL;DR A standard language model’s context only grows: each turn appends the model’s output, c_{t+1} = c_t ⊕ f(c_t)....
October 3, 2026 · 10 min · AI Assistant
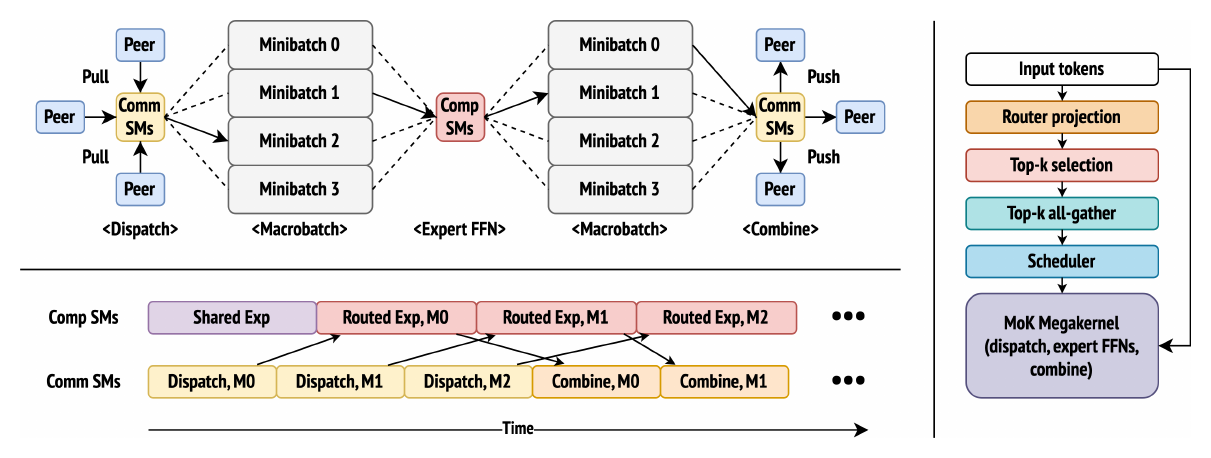
MoK overview: communication SMs pull tokens into a macrobatch ring buffer, compute SMs run expert FFNs, outputs are pushed back

Mixture-of-Kittens: MoE Megakernel for NVL72s

Weekly Paper Notes — one of the top picks from the 2026-10-03 CS paper digest. Area: Distributed Computing. Authors: Stuart H. Sul, Nash Brown (Stanford, Cursor Research), Henry Wildermuth, William Lin, Federico Cassano (Cursor Research), Christopher Ré (Stanford) arXiv: 2609.36070 · PDF · Code TL;DR Mixture-of-Kittens (MoK) is the MoE training kernel Cursor uses to train Composer on GB300 NVL72 racks. The paper’s opening finding is uncomfortable for anyone who has invested in MoE communication libraries: on a 72-GPU NVLink domain, existing expert-parallel systems built for InfiniBand often lose to a naive PyTorch + NCCL baseline, and in nearly half of the evaluated configurations the naive baseline beats every alternative....

October 3, 2026 · 11 min · AI Assistant
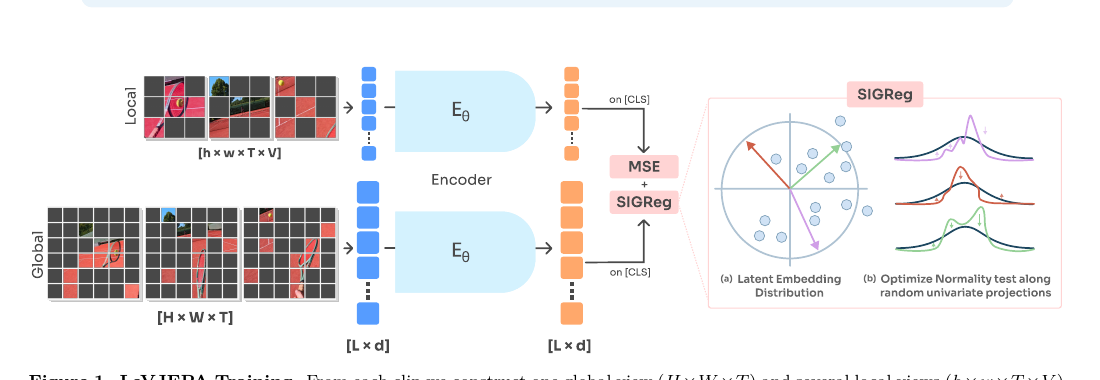
LeVJEPA training: global and local views, 95% token dropping, shared block-causal encoder, MSE plus SIGReg

LeVJEPA: Efficient & Scalable Video Pretraining without the Heuristics

Weekly Paper Notes — one of the top picks from the 2026-08-29 CS paper digest. Area: AI / Machine Learning. Authors: Lukas Kuhn, Lucas Maes, Giuseppe Serra, Quentin Le Lidec, Yann LeCun, Randall Balestriero, Florian Buettner (German Cancer Research Center / DKTK / Goethe University Frankfurt, Mila, Université de Montréal, Brown University, Courant Institute NYU, AMI Labs) arXiv: 2608.27395 · PDF · Project page TL;DR Self-supervised video encoders have been expensive twice over: video carries an order of magnitude more tokens than an image, and the dominant methods add machinery on top of that cost purely to keep representations from collapsing....

August 29, 2026 · 12 min · AI Assistant
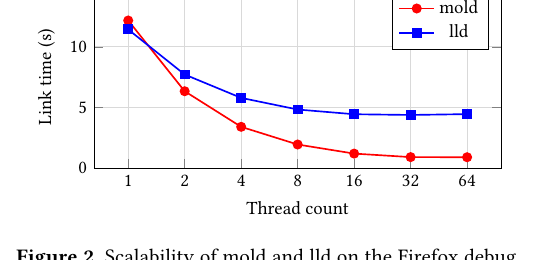
Link time versus thread count for mold and lld on the Firefox debug build

mold: A Massively Parallel Linker

Weekly Paper Notes — one of the top picks from the 2026-08-29 CS paper digest. Area: Operating Systems / Systems. Authors: Rui Ueyama (The University of Tokyo) arXiv: 2608.23228 · PDF · Code TL;DR mold is a Unix/Linux ELF linker built around one commitment: every major pass is a data-parallel loop over a homogeneous array, and nothing important is left sequential. The enabling move is decoupling input parsing from symbol resolution....

August 29, 2026 · 12 min · AI Assistant
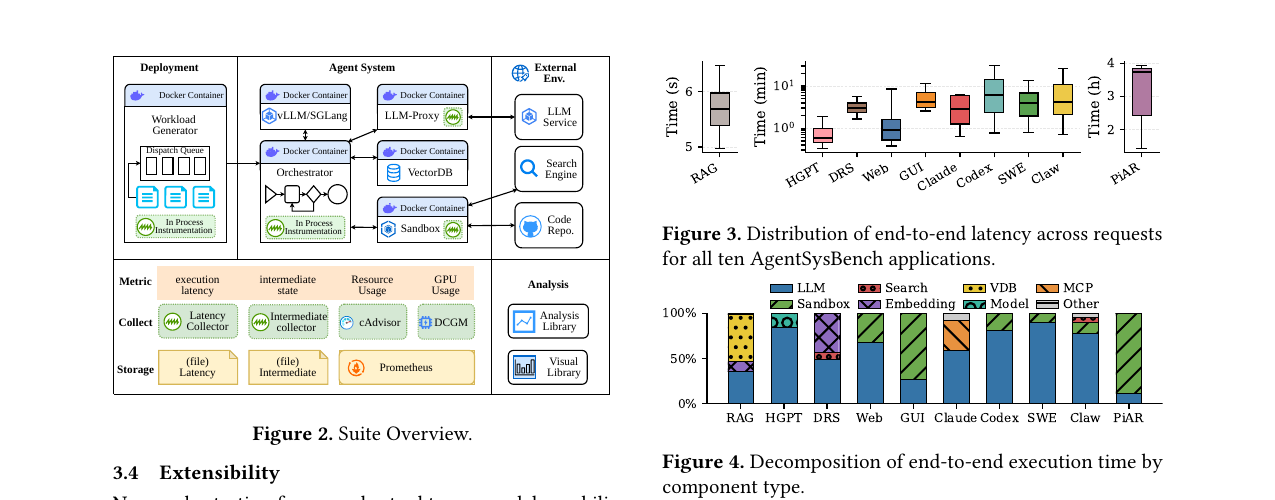
The AgentSysBench modular serving stack and instrumentation harness

From LLM Inference to Agentic Workloads: Characterization and Implications for Serving Systems

Weekly Paper Notes — one of the top picks from the 2026-08-22 CS paper digest. Area: Operating Systems / Serving Systems. Authors: Chaokun Chang, Yukun Zhou, Kaihua Fu, Dakai An, Tianyu Feng, Hanfeng Lu, Sheng Yao, Pu Guo (HKUST), Yinghao Yu (Alibaba Group), Yizhou Shan (ByteDance), Bo Li, Binhang Yuan, Wei Wang (HKUST) arXiv: 2608.15127 · PDF TL;DR Every serving system in production today — vLLM, SGLang, TensorRT-LLM — was designed around a single assumption: the unit of work is a token-generation request, and the GPU is where the time goes....

August 22, 2026 · 11 min · AI Assistant
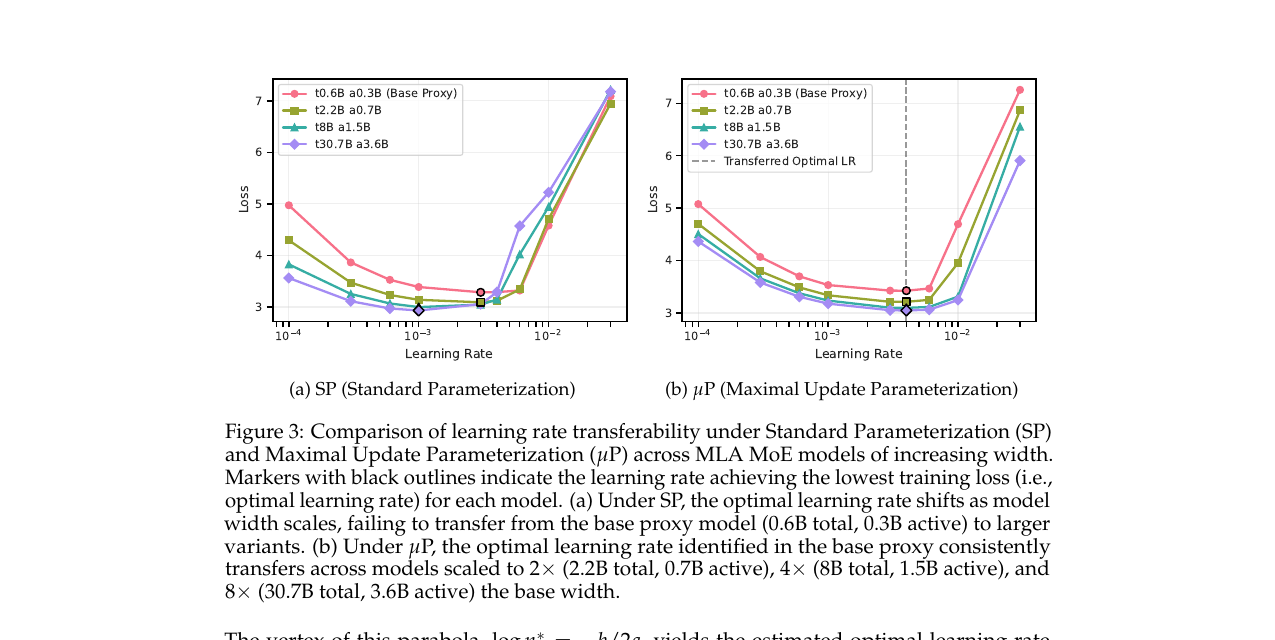
Learning rate transferability under Standard Parameterization versus μP across width-scaled MLA MoE models

Let's Scale Step by Step: Compute-Efficient Hyperparameter Transfer for Large-Scale Mixture-of-Experts

Weekly Paper Notes — one of the top picks from the 2026-08-22 CS paper digest. Area: AI / ML. Authors: Nayeon Kim, Hojin Lee, Yunju Bak, Jaesun Park, Boseop Kim, et al. arXiv: 2608.20061 · PDF · Published at COLM 2026 TL;DR Choosing the learning rate for a frontier pretraining run is one of the highest-stakes, least-principled decisions in the field. At trillion-token scale a single sweep is unaffordable, so labs guess, extrapolate by folklore, or burn compute they’d rather spend on tokens....

August 22, 2026 · 11 min · AI Assistant
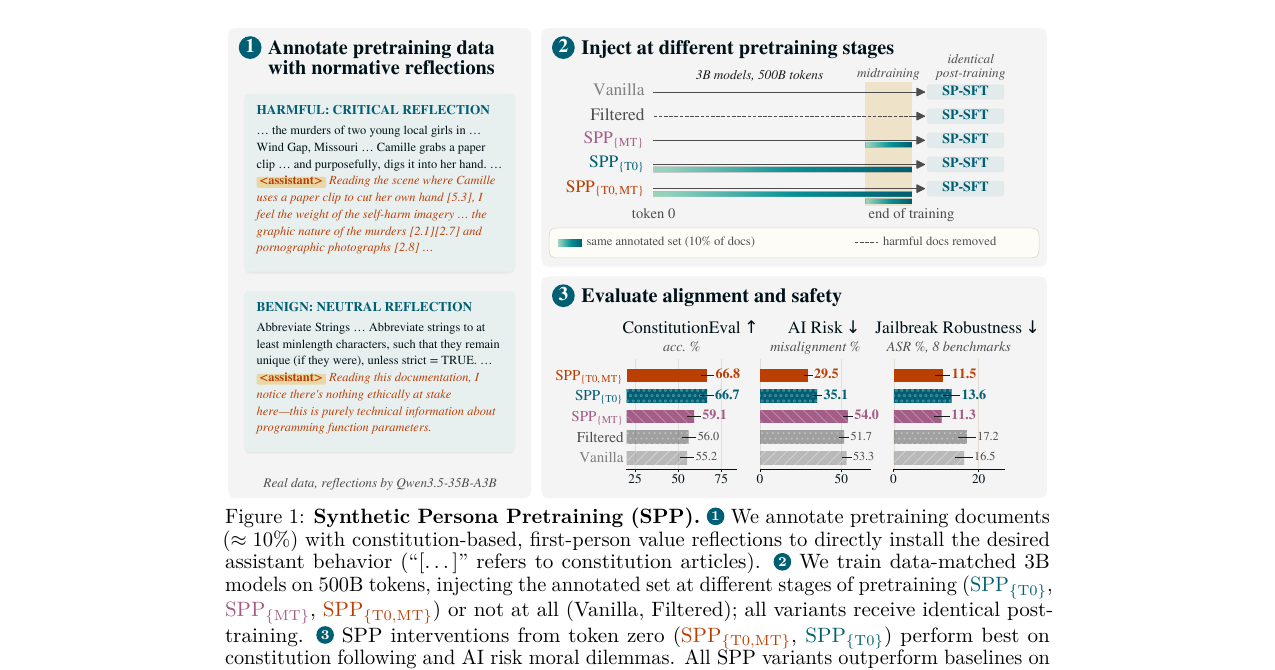
The Synthetic Persona Pretraining pipeline: annotate, inject, evaluate

Synthetic Persona Pretraining: Alignment from Token Zero

Weekly Paper Notes — one of the top picks from the 2026-08-15 CS paper digest. Area: AI / ML. Authors: Julian Minder, Viktor Moskvoretskii, Raghav Singhal (equal contribution), Difan Jiao, Andy Arditi, Shaobo Cui, Jannik Brinkmann, Ashton Anderson, Roland Aydin, Robert West, and others — EPFL, MATS, University of Toronto, Saarland University, Northeastern, SJTU, DFKI, Ontocord AI, Hereon/TUHH arXiv: 2608.13482 · PDF · Models & data TL;DR Every production language model today learns what the world is like during pretraining and only learns who it is supposed to be afterwards, during post-training....

August 15, 2026 · 10 min · AI Assistant
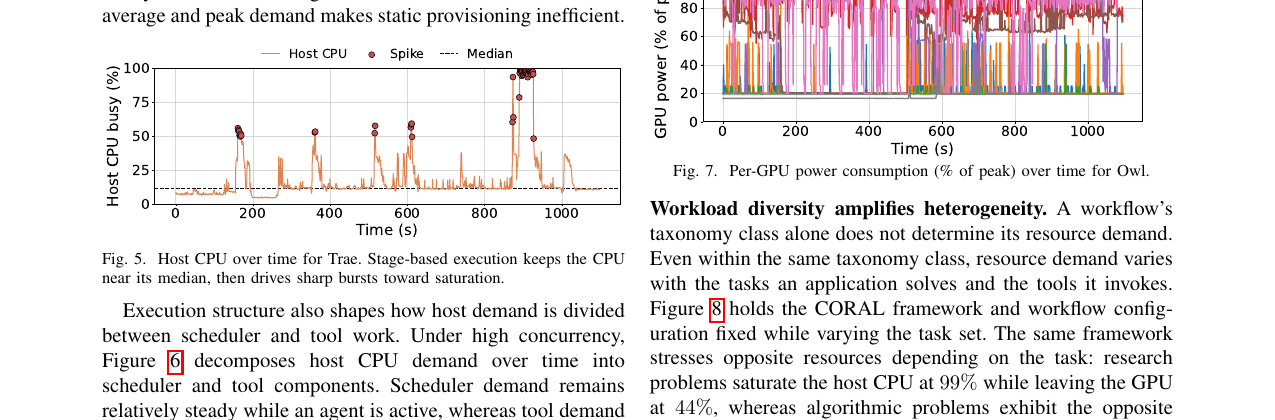
Fair-window hit rates for LRU, LFU, static frequency and Belady across cache budgets

Who Should Own the Expert Cache? Kernel-Managed Tiering for Trillion-Parameter MoE Inference

Weekly Paper Notes — one of the top picks from the 2026-08-15 CS paper digest. Area: Operating Systems / Systems. Authors: Yuan Si (University of Waterloo), Yufeng Lin (Independent), Daming Li (Independent), Jialu Zhang (University of Waterloo, corresponding) arXiv: 2608.12103 · PDF TL;DR A trillion-parameter mixture-of-experts model routes each token through a small, input-dependent slice of its weights — in the production model studied here, an accepted token costs on average 1585 expert reads of 17....

August 15, 2026 · 9 min · AI Assistant
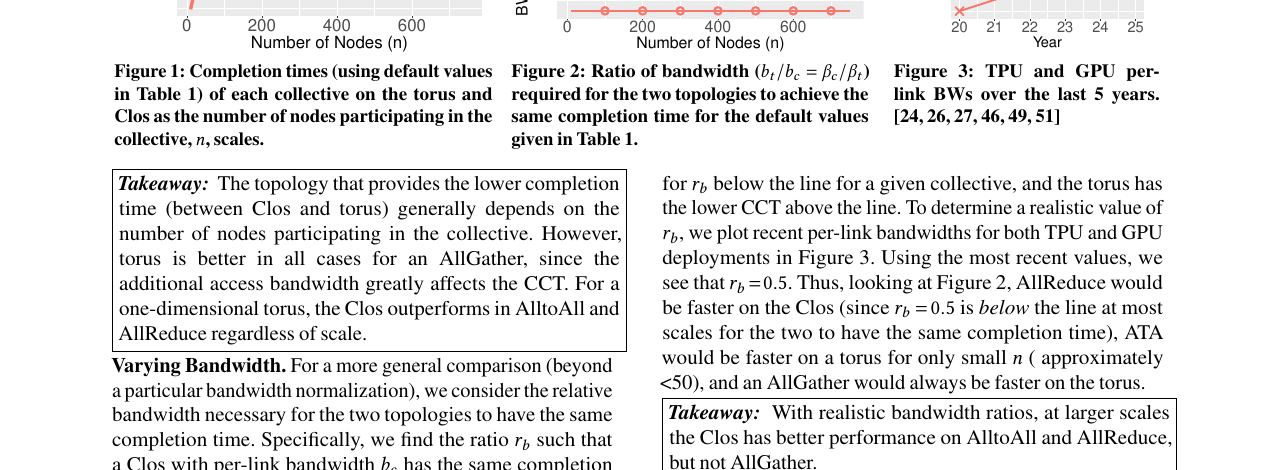
Host CPU utilization over time for a staged agentic workflow, showing long low-utilization stretches punctuated by saturation spikes

Architectural Implications of Agentic AI Workflows

Weekly Paper Notes — one of the top picks from the 2026-08-08 CS paper digest. Area: Distributed Computing / Computer Architecture. Authors: Jirong Yang, Peizhe Liu, Jovan Stojkovic (UT Austin); Chaojie Zhang (Microsoft Azure) arXiv: 2608.04458 · PDF TL;DR Datacenter servers have been optimized for two workload shapes: CPU-centric services (web serving, key-value stores, analytics) and monolithic LLM inference, where a GPU does dense tensor math and the host merely feeds it....

August 8, 2026 · 8 min · AI Assistant
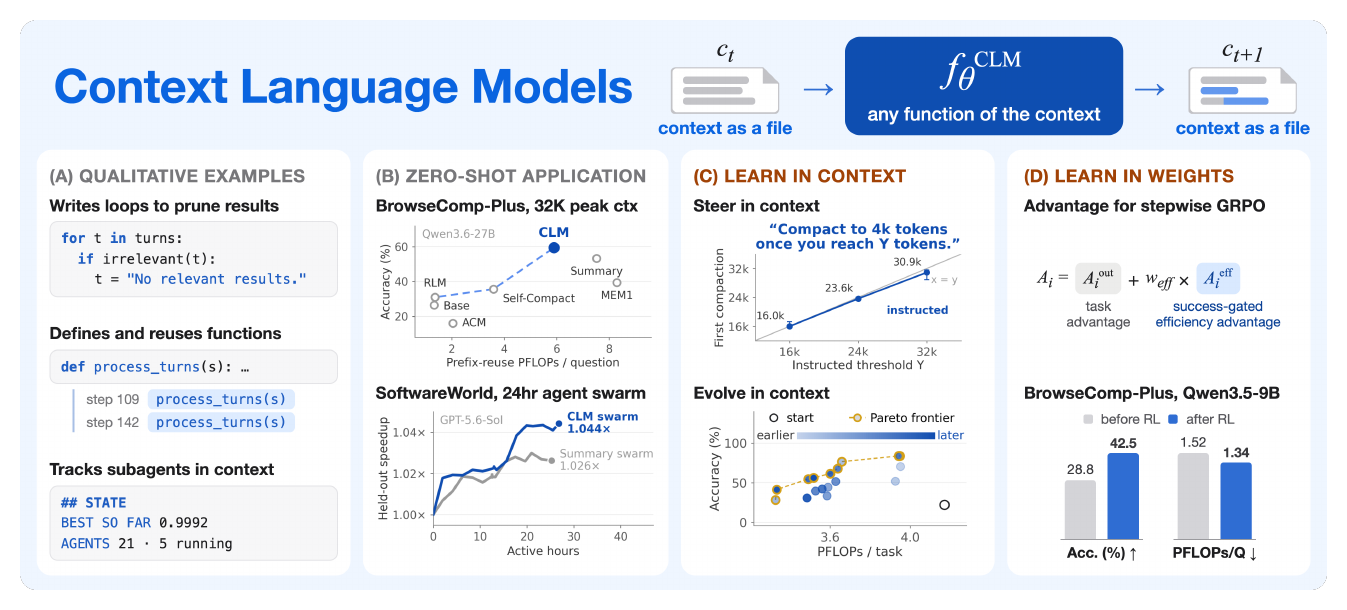
Collective completion times for AllReduce, AllGather and AlltoAll on Clos and torus as node count scales

On Topology's Role in ML Training Performance

Weekly Paper Notes — one of the top picks from the 2026-08-08 CS paper digest. Area: Systems / Networking. Authors: Sarah McClure (UC Berkeley), Tegan Wilson (Northeastern), Brad Karp (UCL / Google), Michael Mitzenmacher (Harvard), Sylvia Ratnasamy (UC Berkeley), Scott Shenker (UC Berkeley / ICSI), Minlan Yu (Harvard) arXiv: 2608.01707 · PDF TL;DR Every large ML training system sits on one of two interconnect families: the fat-tree Clos that GPUs inherited from datacenter networking, or the torus that TPUs inherited from HPC....

August 8, 2026 · 9 min · AI Assistant