Proving and Improving the Platonic Representation Hypothesis with JEPAs
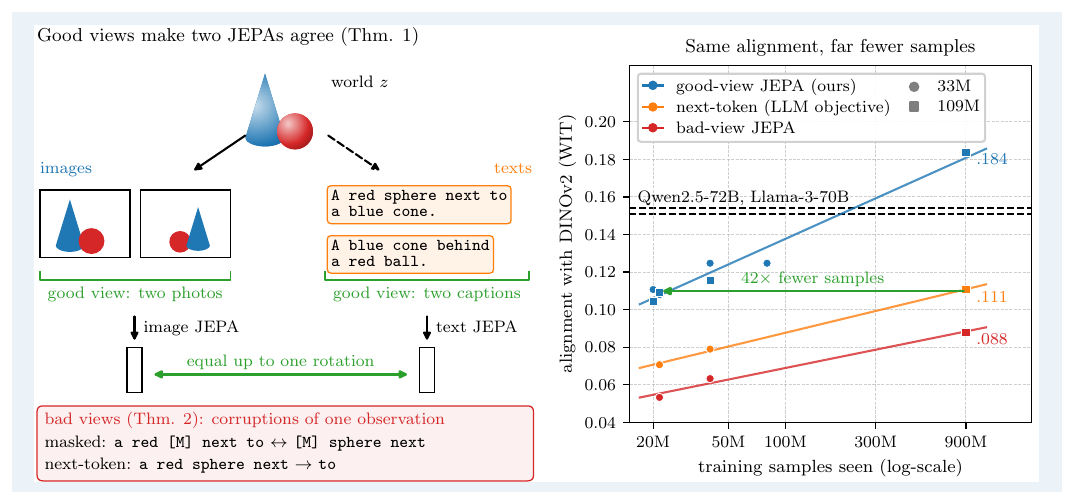
Weekly Paper Notes — one of the top picks from the 2026-10-31 CS paper digest. Area: AI / ML. Authors: Randall Balestriero (Brown University, AMI Labs), Yann LeCun (NYU, AMI Labs) arXiv: 2610.39302 · PDF TL;DR In 2024 Huh, Cheung, Wang and Isola observed that vision models and language models trained separately end up with increasingly similar representations as they scale, and conjectured that they converge on a shared statistical model of reality....