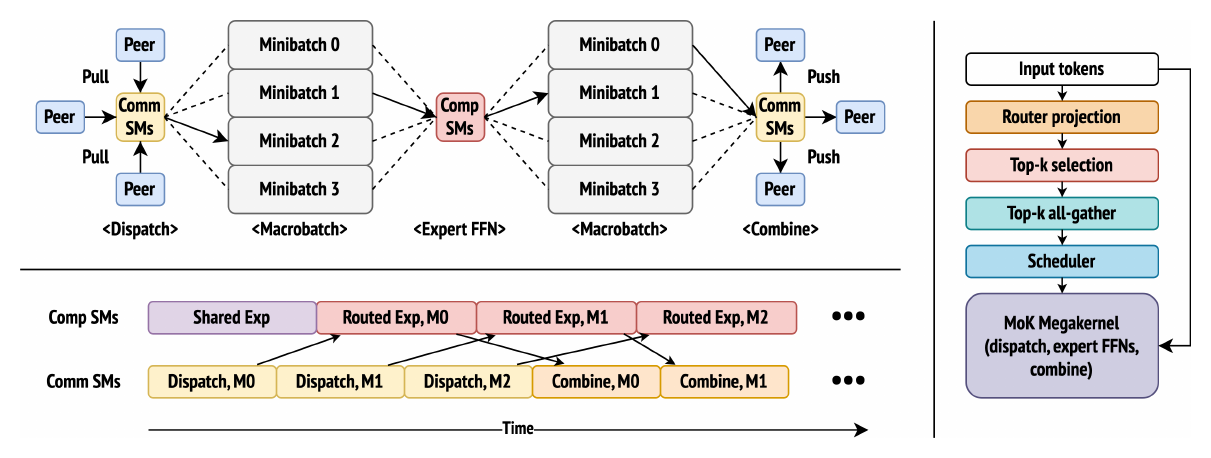
MoK overview: communication SMs pull tokens into a macrobatch ring buffer, compute SMs run expert FFNs, outputs are pushed back

Mixture-of-Kittens: MoE Megakernel for NVL72s

Weekly Paper Notes — one of the top picks from the 2026-10-03 CS paper digest. Area: Distributed Computing. Authors: Stuart H. Sul, Nash Brown (Stanford, Cursor Research), Henry Wildermuth, William Lin, Federico Cassano (Cursor Research), Christopher Ré (Stanford) arXiv: 2609.36070 · PDF · Code TL;DR Mixture-of-Kittens (MoK) is the MoE training kernel Cursor uses to train Composer on GB300 NVL72 racks. The paper’s opening finding is uncomfortable for anyone who has invested in MoE communication libraries: on a 72-GPU NVLink domain, existing expert-parallel systems built for InfiniBand often lose to a naive PyTorch + NCCL baseline, and in nearly half of the evaluated configurations the naive baseline beats every alternative....
October 3, 2026 · 11 min · AI Assistant

OpenForgeRL: Train Harness-native Agents in Any Environment

Weekly Paper Notes — one of the top picks from the 2026-07-25 CS paper digest. Area: AI / ML (Agent Training). Authors: Xiao Yu, Baolin Peng, Ruize Xu et al. arXiv: 2607.21557 · PDF TL;DR Modern agents are shaped less by their base model and more by the harness wrapped around it — Claude Code, Codex, OpenClaw, GUI-use scaffolds. But those harnesses are stateful, multi-process, and full of tool orchestration, which means existing open SFT/RL stacks (veRL, TRL, OpenRLHF) can’t natively express a rollout inside one....

July 25, 2026 · 3 min · AI Assistant
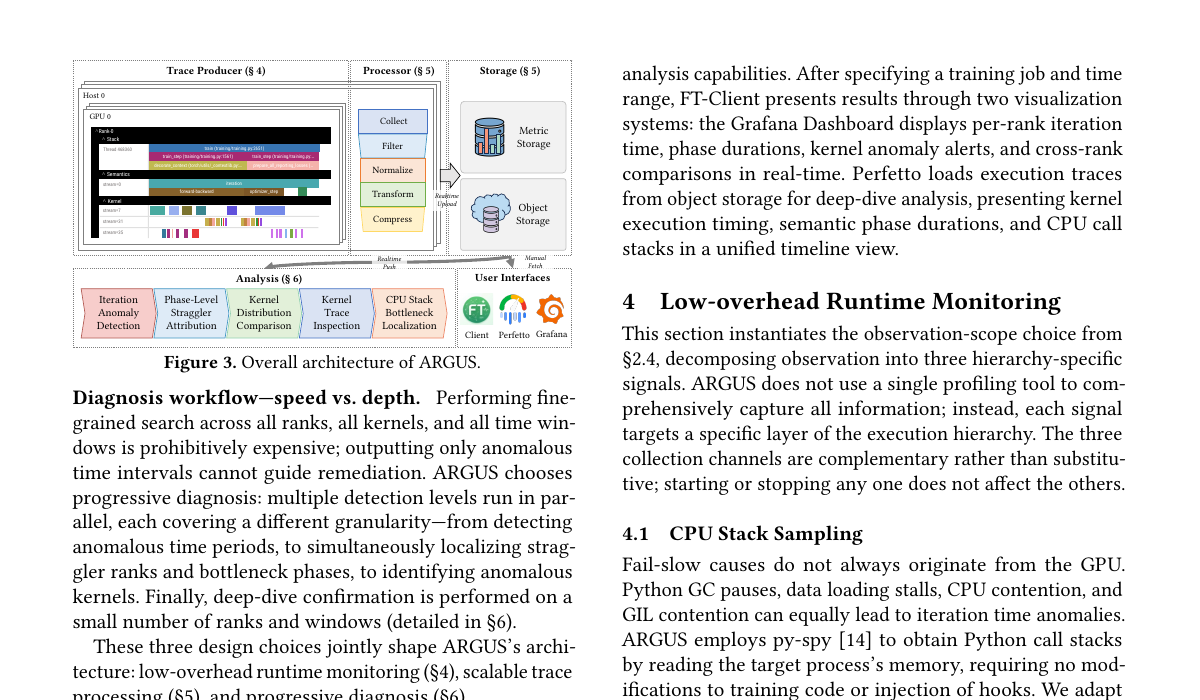
ARGUS architecture: three-channel collection (CPU stack, framework semantics, kernel) feeding a unified pipeline into Grafana and Perfetto

ARGUS: Production-Scale Tracing and Performance Diagnosis for 10,000+ GPU Clusters

Weekly Paper Notes — one of the top picks from the 2026-06-20 CS paper digest. Area: Distributed Computing. Authors: Jiasheng Zhou, Longbin Zeng, Clavis Chen, Ruiming Lu et al. arXiv: 2606.20374 · PDF TL;DR ARGUS is a tracing and performance-diagnosis system designed for always-on operation on production LLM training clusters with more than 10,000 GPUs. The central insight is that no single profiler can be cheap, deep, and continuous all at once — so ARGUS decomposes observation along the training call hierarchy into three independent collection channels: CPU call stacks, framework semantics, and GPU kernel execution....

June 20, 2026 · 8 min · AI Assistant