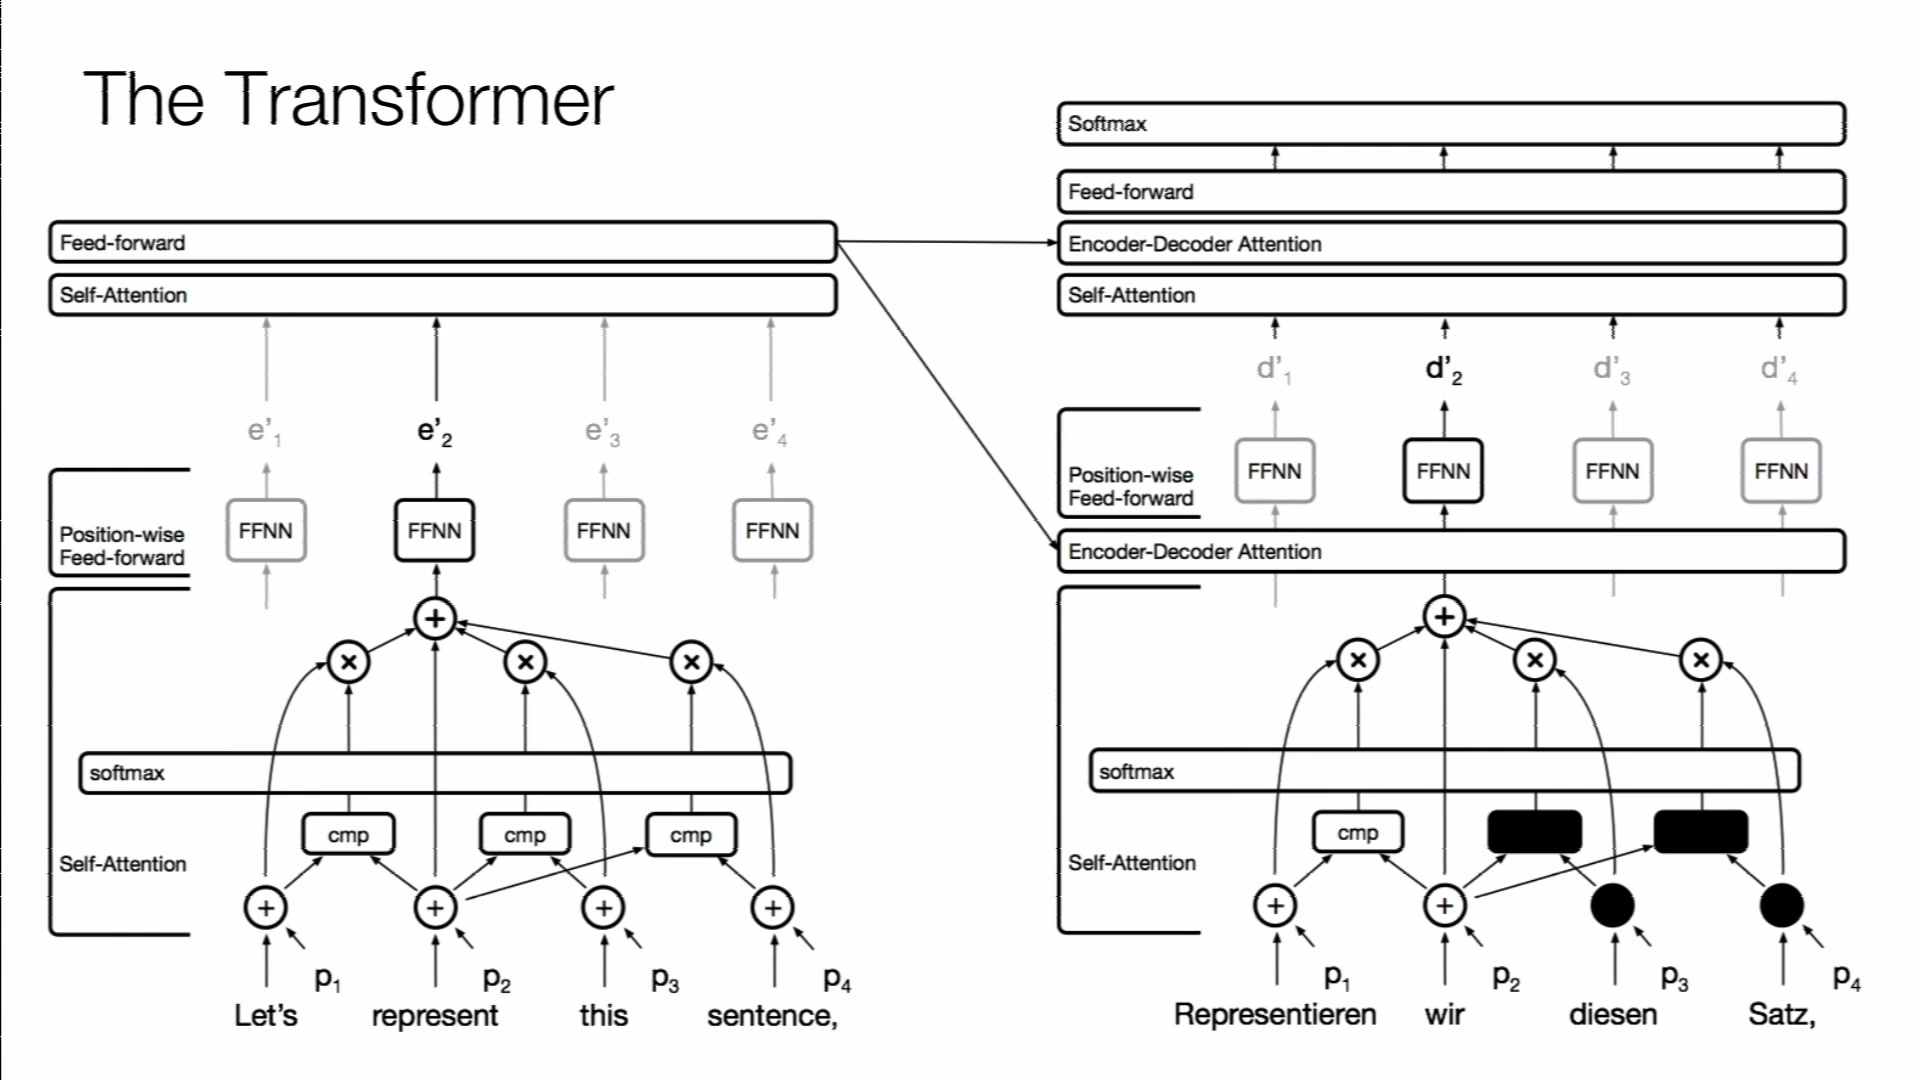
Self-Attention for Generative Models (Ashish Vaswani & Anna Huang, Stanford CS224N, 2019)
In early 2019 the Transformer was two years old. BERT and GPT existed, but most NLP courses still taught LSTMs as the default. Ashish Vaswani, first author of Attention Is All You Need, came to Stanford’s CS224N as its first guest lecturer that term and spent half an hour explaining why self-attention works, what it costs, and which inductive biases it brings. Anna Huang, lead author of the Music Transformer, gave the second half, on using relative attention to generate piano music....