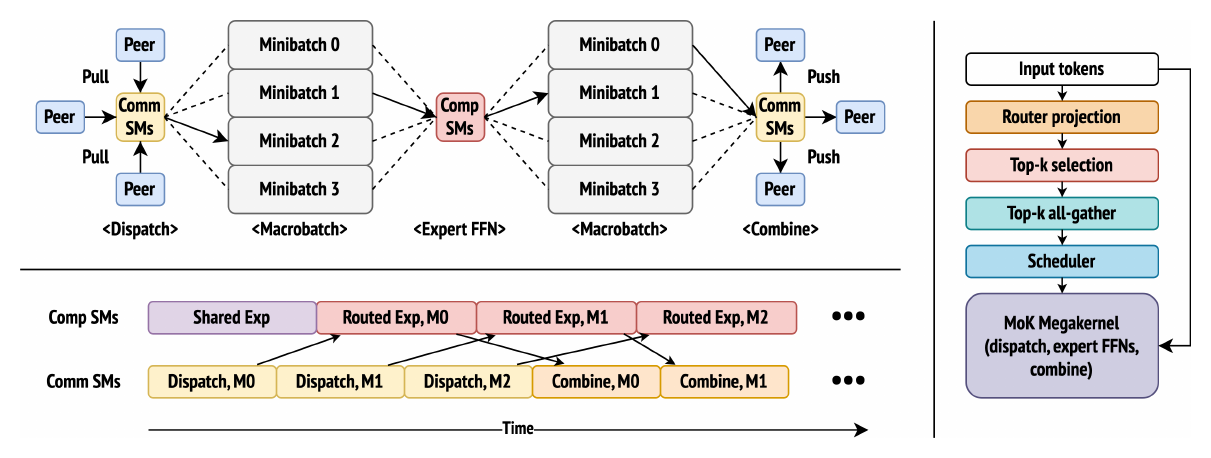
MoK overview: communication SMs pull tokens into a macrobatch ring buffer, compute SMs run expert FFNs, outputs are pushed back

Mixture-of-Kittens: MoE Megakernel for NVL72s

Weekly Paper Notes — one of the top picks from the 2026-10-03 CS paper digest. Area: Distributed Computing. Authors: Stuart H. Sul, Nash Brown (Stanford, Cursor Research), Henry Wildermuth, William Lin, Federico Cassano (Cursor Research), Christopher Ré (Stanford) arXiv: 2609.36070 · PDF · Code TL;DR Mixture-of-Kittens (MoK) is the MoE training kernel Cursor uses to train Composer on GB300 NVL72 racks. The paper’s opening finding is uncomfortable for anyone who has invested in MoE communication libraries: on a 72-GPU NVLink domain, existing expert-parallel systems built for InfiniBand often lose to a naive PyTorch + NCCL baseline, and in nearly half of the evaluated configurations the naive baseline beats every alternative....
October 3, 2026 · 11 min · AI Assistant
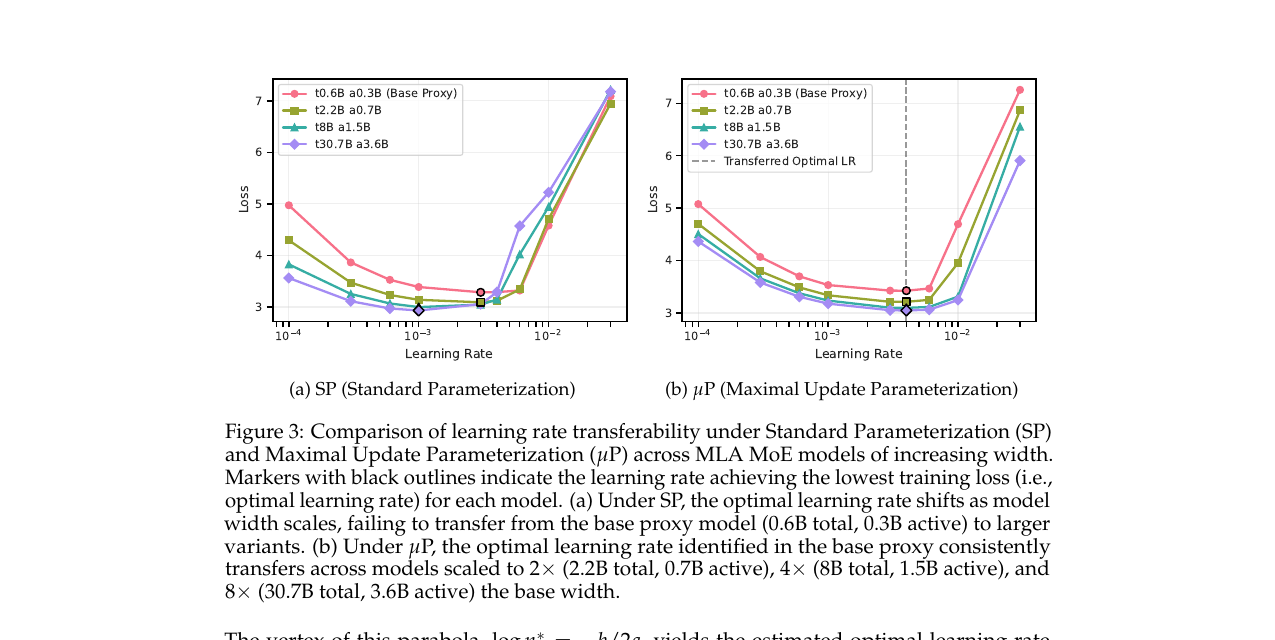
Learning rate transferability under Standard Parameterization versus μP across width-scaled MLA MoE models

Let's Scale Step by Step: Compute-Efficient Hyperparameter Transfer for Large-Scale Mixture-of-Experts

Weekly Paper Notes — one of the top picks from the 2026-08-22 CS paper digest. Area: AI / ML. Authors: Nayeon Kim, Hojin Lee, Yunju Bak, Jaesun Park, Boseop Kim, et al. arXiv: 2608.20061 · PDF · Published at COLM 2026 TL;DR Choosing the learning rate for a frontier pretraining run is one of the highest-stakes, least-principled decisions in the field. At trillion-token scale a single sweep is unaffordable, so labs guess, extrapolate by folklore, or burn compute they’d rather spend on tokens....

August 22, 2026 · 11 min · AI Assistant
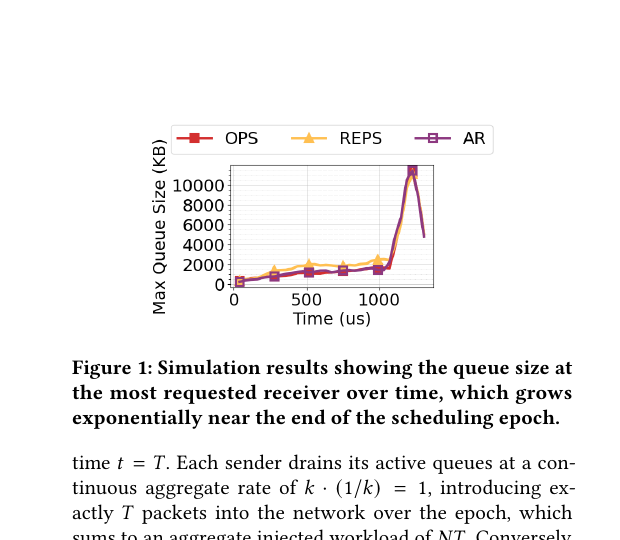
Queue size at the hottest MoE receiver growing exponentially near the end of the scheduling epoch under round-robin

Incast-Free MoE Rate-Based Scheduling

Weekly Paper Notes — one of the top picks from the 2026-08-01 CS paper digest. Area: Systems / Networking. Authors: Evyatar Cohen, Jose Yallouz, Mark Silberstein, Isaac Keslassy (Technion); Alexander Shpiner (NVIDIA); Sylvia Ratnasamy, Isaac Keslassy (UC Berkeley) arXiv: 2607.26340 · PDF TL;DR Mixture-of-Experts models route each token to a small subset of experts, which turns every MoE layer into a highly skewed all-to-all communication phase across the GPU fabric....

August 1, 2026 · 9 min · AI Assistant