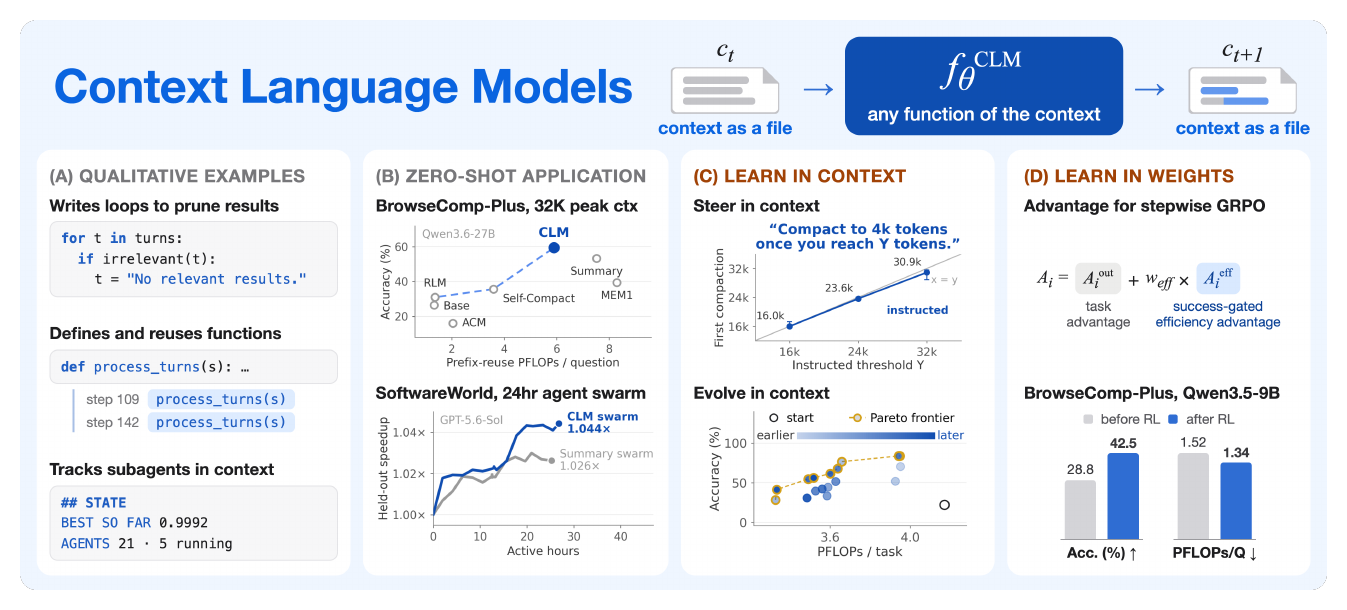
Overview of Context Language Models: emergent context edits, results on BrowseComp-Plus and Software World, steering and skill evolution, and RL

Context Language Models

Weekly Paper Notes — one of the top picks from the 2026-10-03 CS paper digest. Area: NLP. Authors: Rulin Shao, Shannon Zejiang Shen, Junjie Oscar Yin, Yuetai Li, Minheng Wang, Hamish Ivison, Radha Poovendran, Nathan Lambert, Teng Xiao, Mike Lewis, Wen-tau Yih, Luke Zettlemoyer, Pang Wei Koh (University of Washington, Meta Superintelligence Labs, MIT, Trillium Labs) arXiv: 2609.37725 · PDF · Code TL;DR A standard language model’s context only grows: each turn appends the model’s output, c_{t+1} = c_t ⊕ f(c_t)....

October 3, 2026 · 10 min · AI Assistant

You Only Index Once: Cross-Layer Sparse Attention with Shared Routing

Weekly Paper Notes — one of the top picks from the 2026-06-06 CS paper digest. Area: NLP / Systems-for-ML. Authors: Yutao Sun, Yanqi Zhang, Li Dong, et al. (Microsoft Research Asia) arXiv: 2606.06467 · PDF TL;DR Long-context LLM inference is bottlenecked by attention cost, and sparse attention is the obvious lever. The two existing families both disappoint in practice: block-sparse patterns (sliding window, dilated, etc.) give clean speedups but lose quality, while token-sparse patterns (top-k over the KV cache) preserve quality but spend most of the budget deciding which tokens to attend to — the routing itself becomes the bottleneck....

June 6, 2026 · 6 min · AI Assistant