A Fix for Softmax and Cross-Entropy
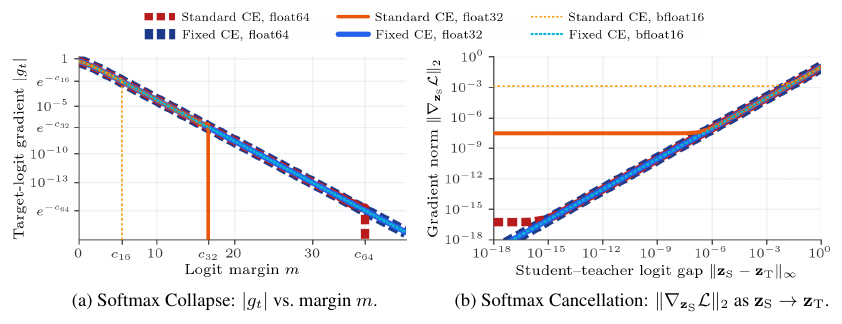
Weekly Paper Notes — one of the top picks from the 2026-10-24 CS paper digest. Area: AI / ML. Authors: Jonathan T. Barron, Dan Gnanapragasam, Michael Tschannen (Google DeepMind) arXiv: 2610.31642 · PDF TL;DR Every deep learning framework computes softmax and cross-entropy the same way: subtract the largest logit so exp can’t overflow, then normalise. That trick fixes overflow and leaves two quieter bugs in place. The first, which the authors call Softmax Collapse, hits when the model is very confident....